On this page
The choice of Vector database for RAG pipelines can make or break your agent’s core paradigm.
A well-chosen vector store recalls relevant documents with low query latency, and a poor choice can slow down responses and cause agents to hallucinate or fail.
However, finding the correct vector database for your RAG pipeline is not a simple task. You have to test each system’s semantic accuracy, query throughput, and metadata filtering under realistic loads.
- AI engineers on your agent
- Set up in minutes
- No credit card
But don’t worry, we’ve done the testing, so you don’t have to.
For this article, we evaluated and tested the 10 best vector databases for RAG pipelines, assessing them under various parameters and comparing their strengths and weaknesses in real-world agentic AI workflows.
TL;DR for Top Vector Databases for RAG Pipelines
- Pinecone: A fully-managed cloud vector DB. Known for enterprise-grade reliability and scalability.
- Turbopuffer: An S3-based serverless vector + text search engine. Cost-effective with built-in hybrid search even on low tiers.
- Redis (Redis Search): In-memory vector search built into Redis 8. Ultra-low-latency queries and flexible schema.
- Weaviate: An open-source vector database. Features gRPC and REST APIs and a modular design.
- Qdrant: An open-source Rust vector database. Excels at real-time embedding search with rich JSON-based payload filtering.
- Milvus (Zilliz Cloud): Open-source, GPU-accelerated vector DB. Optimized for massive scale and high-throughput serving.
- Vespa: A full-featured search platform with vector support. Designed for billion-scale deployments.
- pgvector (PostgreSQL): A Postgres extension for vector columns. Brings HNSW/IVF indexing to PostgreSQL’s relational engine.
- Elasticsearch: A proven distributed search engine. Combines Elasticsearch’s mature text querying and filtering with vector fields.
- MongoDB (MongoDB Vector Search): A document database with built-in vector search. Supports hybrid full-text and embedding search, as well as rich JSON filtering.
Our Evaluation Criteria to Pick the Top Vector Databases for RAG Pipelines
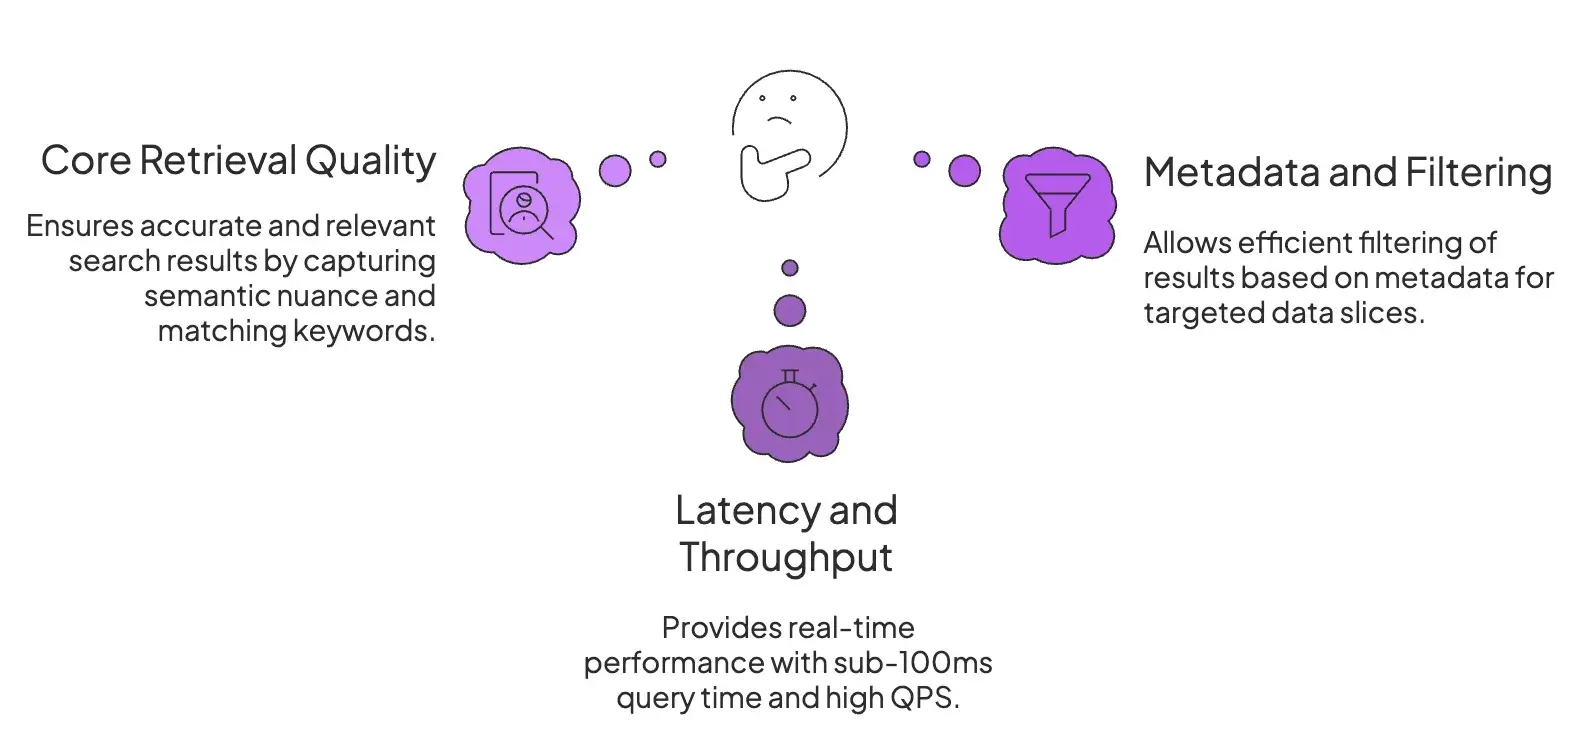
When comparing vector databases for RAG, our evaluation focused on three core pillars that matter most in a RAG pipeline.
1. Core Retrieval Quality
Retrieval quality is about finding the most relevant context for a query.
Early systems struggled when a query for ‘Apple’ returned documents about the fruit instead of the company. One of our first evaluation criteria was to determine how accurately the system surfaces the right embeddings for a query.
For that, we looked for tools that support:
- Proven Approximate Nearest Neighbor (ANN) algorithms like HNSW and IVF.
- Tuning options that affect recall and relevance.
- Hybrid search capabilities that combine dense vector (semantic) search with sparse vector (lexical) search, like BM25.
Essentially, we evaluated whether the RAG tool can capture semantic nuance while still matching the exact keywords and acronyms that are often critical for relevance.
2. Latency and Throughput
Latency refers to the time elapsed between when a query is received and the output is provided.
Real-time or interactive RAG apps like AI agents and chatbots demand sub-100ms query times, even under high QPS (queries per second) and with datasets scaling to billions of vectors.
We also considered operational factors like ease of deployment, language SDKs, community support, and data persistence for all tools.
3. Metadata and Filtering
Raw vector search is rarely sufficient for production applications. Filtering is crucial for restricting RAG to relevant data slices, like date, customer ID, document source, or security permissions.
We evaluated tools for:
- Does it allow you to pre-filter or post-filter results?
- Does it support Boolean filters and faceted queries?
- Is it able to apply these metadata filters efficiently without hammering performance?
What are the Best Vector Databases for RAG Pipelines?
Here is a quick summary of the 10 best vector databases we tested for building RAG pipelines:
| Tool | Best For | Key RAG Features | Pricing Model |
|---|---|---|---|
| Pinecone | Teams that want a fully managed, serverless database for rapid development. | - Serverless architecture - Hybrid search and real-time indexing - Advanced metadata filtering | Free tier, paid plans start at $20/month. |
| Turbopuffer | RAG at a massive scale, where cost-efficiency is the top priority. | - Object-storage architecture - Combined vector and full-text search - High write throughput | Plans start at a $16/month minimum. |
| Redis | Applications needing ultra-low latency retrieval for real-time RAG. | - In-memory performance - Flexible indexing (HNSW/FLAT) - Hybrid queries, multi-purpose datastore | Open-source; cloud plans start at $5/month. |
| Weaviate | Developers looking for an AI-native, open-source database with built-in vectorization. | - Integrated vectorization modules - Advanced hybrid search - Multimodal capabilities | Open-source; free cloud plan, paid cloud plans start at $45/month. |
| Qdrant | RAG systems require high performance with complex metadata filtering. | - Advanced pre-filtering - Rust-based performance - Vector compression | Open-source and a free cloud tier; paid cloud plans are usage-based and billed hourly. |
| Milvus | Enterprise-grade RAG deployments are needed with high scalability. | - Distributed architecture - Diverse index support and enterprise features (multi-tenancy, RBAC) | Open-source, with managed cloud plans including a free tier and dedicated options. |
| Vespa | Sophisticated RAG applications where custom, machine-learned ranking is critical. | - Unified search and ranking engine - Native tensor support - Real-time performance at scale | Open-source, with usage-based cloud pricing based on allocated resources. |
| pgvector | Teams already using PostgreSQL who want to add RAG capabilities simply. | - Integration with PostgreSQL - Leverages SQL and ACID compliance - HNSW/IVFFlat indexing | Free open-source extension; costs are for PostgreSQL hosting. |
| Elasticsearch | Enterprise RAG systems that require best-in-class hybrid search. | - Mature hybrid search (BM25 + vector) - Distributed scalability - Rich filtering and aggregations | Free and open tier, with cloud plans starting at $99/month. |
| MongoDB | Developers in the MongoDB ecosystem building RAG on a flexible document model. | - Integrated into the core database - Hybrid search with MQL - Scalable via Search Nodes. | Free tier, with usage-based pricing for Atlas clusters. |
1. Pinecone
Pinecone is a fully managed, cloud-native vector database designed for ease of use and massive scale. Its serverless architecture makes it a popular choice for RAG applications, as it abstracts away scaling constraints and infrastructure management and allows developers to focus on building.
Features
- Get low-latency, fast similarity search over dense embeddings without choosing an ANN index yourself. Pinecone selects the indexing algorithm automatically based on data size and upgrades it in the background.
- You can attach arbitrary key-value metadata to each vector and use boolean filters in queries. Pinecone also supports namespaces within an index for multi-tenant isolation or sharding.
- Supports real-time indexing of vectors, allowing RAG applications to access the freshest data without delays or re-indexing batches.
- Apply rich metadata filtering during the ANN search to retrieve only vectors that match the specified criteria, with minimal impact on latency.
Pricing
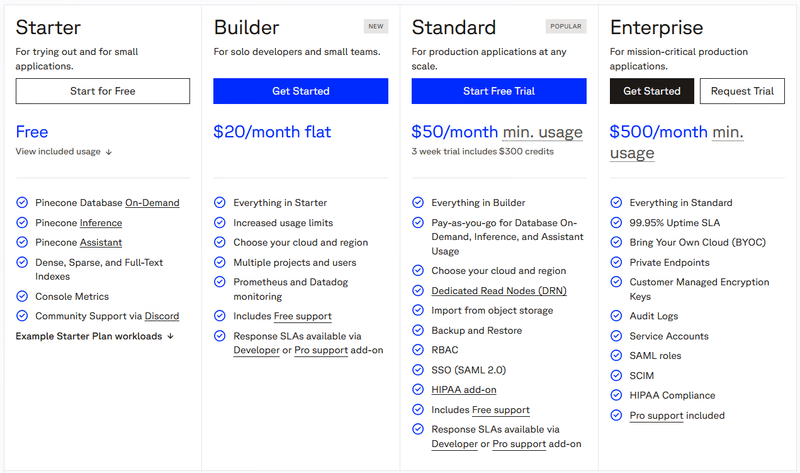
Pinecone offers a usage-based pricing model with a free ‘Starter’ tier. The Starter plan (no credit card required) includes up to 2GB of storage, 2 million write units, and 1 million read units. Beyond free usage, it has three paid plans:
- Builder: $20 per month flat
- Standard: $50 per month minimum spend
- Enterprise: $500 per month minimum spend
Pros and Cons
The major pro is Pinecone’s simplicity and fully managed, serverless nature, which offloads infrastructure concerns for RAG developers. Its real-time indexing and powerful filtering are built for production. Pinecone also handles large workloads with strong SLA support.
However, Pinecone is a closed-source SaaS. If you need on-premises, Pinecone may not be the right fit, and running it in your own AWS, GCP, or Azure account (BYOC) requires the Enterprise plan. Additionally, scaling beyond the free tier can become costly compared to open-source alternatives.
2. Turbopuffer
Turbopuffer is a serverless vector and full-text search engine built on object storage. It is designed for extreme cost-effectiveness and scalability, making it an intriguing option for RAG pipelines at a massive scale.
Features
- Supports both dense vector similarity and BM25 keyword indexes, allowing RAG applications to combine semantic and lexical relevance in one system.
- Access to storage solutions like S3/Blob makes it cheaper to store large volumes of vector data compared to memory or SSD-based solutions.
- Features a pre-warming function that pre-fetches and caches data in memory, allowing even cold-start requests to be fast.
- Turbopuffer scales to millions of namespaces, enabling natural data partitioning for multi-tenant RAG applications where each tenant's data is isolated for performance and security.
Pricing
Turbopuffer offers plan-based pricing with a minimum monthly spend. It has three plans:
- Launch: $16 per month
- Scale: $256 per month
- Enterprise: From $4,096 per month
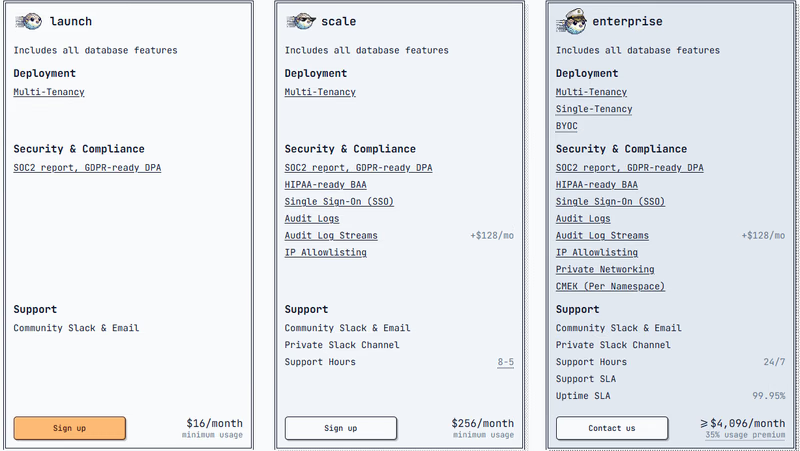
👀 Note: Within these tiers, usage costs are based on storage, writes, and queries.
Pros and Cons
Turbopuffer stands out for price-performance. A disruptive cost model for large-scale RAG deployment. Enterprise readiness, like SOC 2 and GDPR compliance, and community support come standard.
The main downside is the trade-off in latency; cold queries are slow (p50 of 874ms on a 10-million-vector namespace) and writes take around 165ms at p50, which may not be suitable for all real-time RAG use cases. Also, there’s no free tier, so even small projects pay the $16 monthly minimum. It is not open-source, so you rely on Turbopuffer’s cloud unless you’re on the Enterprise plan, which can deploy into your own AWS, GCP, or Azure account.
3. Redis
Redis is a well-known data store that offers vector search as a natural extension of its in-memory engine. Its exceptional speed makes it a strong candidate for low-latency RAG applications, especially for teams already using Redis in their stack.
Features
- Being in-memory, vector queries and filters execute with ultra-low latency in the single-digit milliseconds.
- Supports multiple vector search algorithms, including FLAT for exact nearest neighbor search and HNSW for approximate nearest neighbor (ANN) search.
- Beyond vector search, Redis can serve as a semantic cache or an LLM session manager within the same RAG pipeline.
- Perform hybrid searches that combine text queries with vector similarity filtering on numeric, geographic, tag, and text fields. You can embed Boolean logic (AND/OR) around vector queries for complex filters.
Pricing
Redis is open-source, so the core vector search capability is free to use on your own hardware. For managed service, Redis offers three pricing plans:
- Free: $0 for a 30 MB database
- Essentials: From $0.007 per hour ($5 per month)
- Pro: From $0.014 per hour ($200 per month minimum)
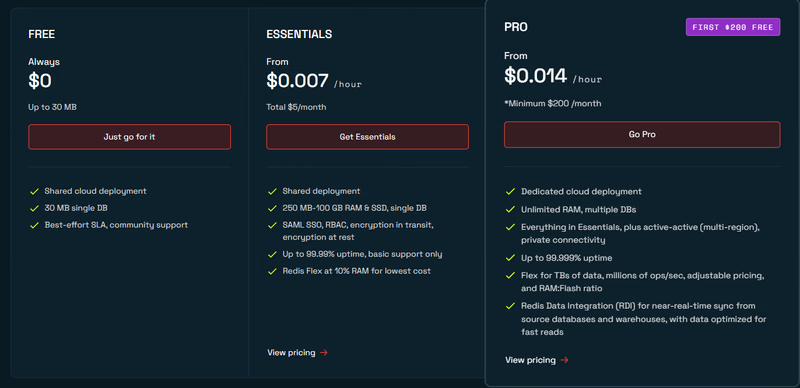
👀 Note: Pricing is primarily based on memory (RAM) and can scale up significantly for larger datasets.
Pros and Cons
Redis’s biggest pro is its raw speed, delivering sub-millisecond latency that is hard to beat. Its multi-model nature means you can manage your embeddings alongside other app data in one system.
The primary con is its in-memory nature, which makes it expensive for storing large vector datasets. The RAM requirement grows with data size. Moreover, scaling Redis often requires sharding, which you may need to design yourself.
4. Weaviate
Weaviate is an open-source, AI-native vector database built with a graph-like class schema. The design helps you scale and provide more flexibility in RAG workflows. It offers a rich feature set, including built-in vectorization modules and advanced search capabilities.
Features
- Every query runs against a typed collection schema through the gRPC API that Weaviate's client libraries use. You can filter on any property and include vector-based search in the same query.
- Built-in Vectorization Modules automatically vectorize text and image data at import time through integrations with models from OpenAI, Cohere, HuggingFace, and others.
- Supports hybrid queries that merge keyword (BM25) search with vector similarity in a single API call.
- You can run Weaviate in single- or multi-node clusters, either self-hosted or in Weaviate Cloud. It uses HNSW internally by default for vector indexing.
Pricing
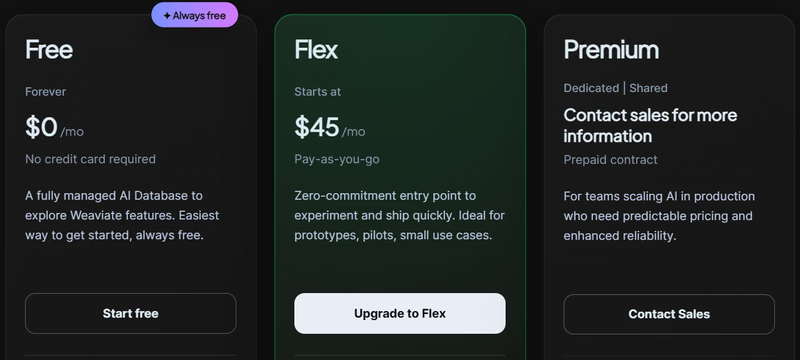
Weaviate’s Community Edition is open-source (BSD-3), so you can self-host it for free. Weaviate Cloud has a free plan (one cluster, up to 100,000 objects) and two paid plans:
- Flex: Starts at $45 per month
- Premium: Custom pricing on a prepaid contract (from $400 per month)
Pros and Cons
Weaviate is very flexible and developer-friendly for RAG. Its core value is its AI-native design, particularly the built-in vectorization modules and its powerful hybrid search. Multi-modality is a first-class citizen: you can index images, text, and other content seamlessly.
However, defining the schema correctly is critical. Performance can lag behind some bare-metal solutions at a very large scale. Also, while it has built-in vectorizers, the module costs can add up.
5. Qdrant
Qdrant is an open-source vector search engine written in Rust. It’s purpose-built for RAG applications where speed and memory safety are paramount.
Features
- Filter vectors using JSON payload fields such as range, equality, list, and geospatial to ensure high performance even with complex metadata filters.
- Built-in quantization to compress vectors, significantly reducing memory usage and cost while maintaining high search performance.
- Use HNSW indexing for fast k-NN searches on large datasets, and build those indexes on GPUs to speed up indexing.
- Support storing multiple vectors per document (e.g., for title and body) and can handle sparse vectors for hybrid search.
- Use its Recommendation API for multi-vector retrieval to influence results or blend recommendations.
Pricing
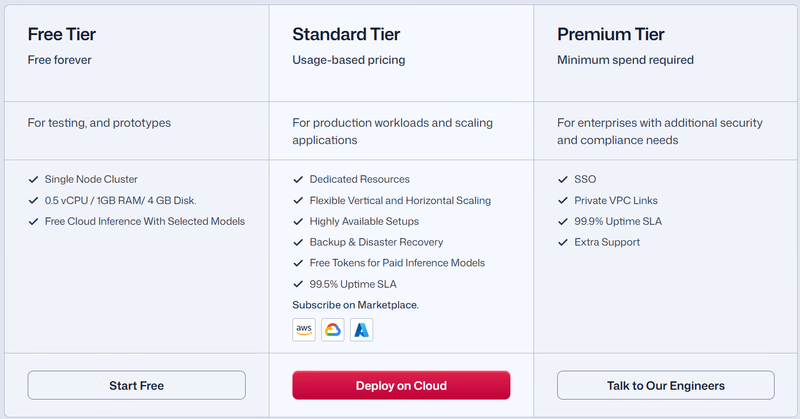
Qdrant itself is open-source. The Qdrant Cloud service offers a free 1GB cluster. Beyond free usage, managed clusters are usage-based and billed hourly for the vCPU, memory, and storage you provision. Qdrant doesn’t list prices for these plans, so use its pricing calculator to estimate a cluster:
- Standard: Usage-based pricing
- Premium: Minimum spend agreed with Qdrant
- Hybrid Cloud: Custom pricing
- Private Cloud: Custom pricing
Pros and Cons
Qdrant’s open-source nature and flexible deployment are strong advantages. Many teams find their Rust core is efficient and simple to get running via Docker. An ideal choice for complex RAG applications that need to slice and dice data.
However, some of its newer capabilities depend on where you run it. Built-in embedding (Cloud Inference) is only available on Qdrant Cloud, so self-hosted users generate vectors client-side with FastEmbed or their own models. Native BM25 scoring on full-text indexes only arrived in v1.20 (October 2026), so its keyword search is newer than what you get from engines like Elasticsearch. Also, Qdrant doesn’t publish list prices for its paid cloud tiers, which makes costs harder to compare up front.
6. Milvus
Milvus is a highly scalable, open-source vector database. Built with a cloud-native, distributed architecture that separates compute and storage, Milvus can scale to handle billions or even trillions of vectors.
It’s a graduate project of the LF AI & Data Foundation, making it a popular choice for enterprise-grade RAG systems.
Features
- Supports HNSW, IVF, PQ, CAGRA index types and similarity metrics (L2, IP, Cosine). You can choose the best index for trade-offs between recall and speed.
- Use up to 10 vector fields per collection with support for a wide range of data types, including sparse vectors for full-text search.
- Allows scalar and string filtering on fields with wildcards (prefix/infix/suffix) on metadata, which is useful for text-based filters.
Pricing
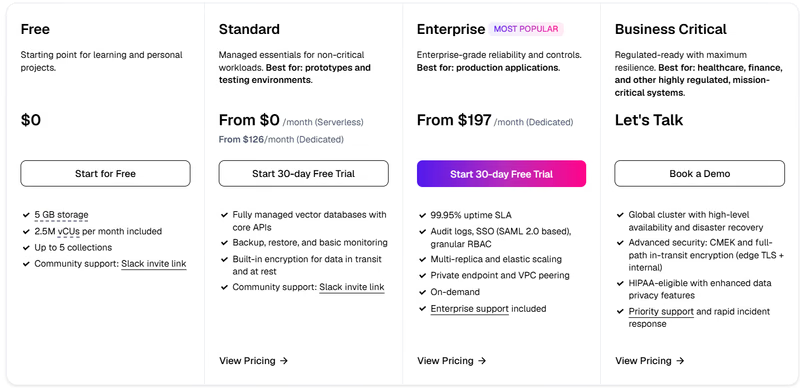
Milvus itself is open-source. Zilliz offers Milvus as a managed service. The free tier includes 5GB of storage (~1 million vectors). Beyond that, you can choose from three paid plans:
- Standard: Pay-as-you-go on Serverless ($4 per million vCUs plus $0.30 per GB of storage per month), or from $126 per month on Dedicated
- Enterprise: From $197 per month on Dedicated
- Business Critical: Custom pricing
Zilliz also offers BYOC deployments with custom pricing.
Pros and Cons
Milvus’s support for GPU indexing means you can achieve very high QPS on massive datasets. The multiple index options let you tune for recall or speed. The open-source community is large and active.
On the contrary, Milvus can be complex to operate. Its clustering and resource settings require careful tuning, or you rely on the cloud product. Also, Milvus’s built-in text filtering is not as intuitive as a SQL-like query language; you must define proper field indexes and use expressions.
7. Vespa
Vespa is a powerful open-source engine for big data and AI. It functions as both a fully-featured search engine and a vector database. It’s designed for real-time applications that combine vector search, lexical search, and machine-learned ranking at scale.
Features
- Supports native tensor operations that allow implementing more complex retrieval and ranking models, like multi-vector representations, directly within the database.
- Supports nested conditions, OR/AND chains, and faceted filters on any field. This makes multi-condition RAG queries straightforward.
- Vespa can run neural models at query time. It can apply re-rankers or embed models on the fly.
- Vespa has client libraries for Python and Java, and you query with YQL, Vespa's SQL-like query language, or send the same query as JSON.
Pricing
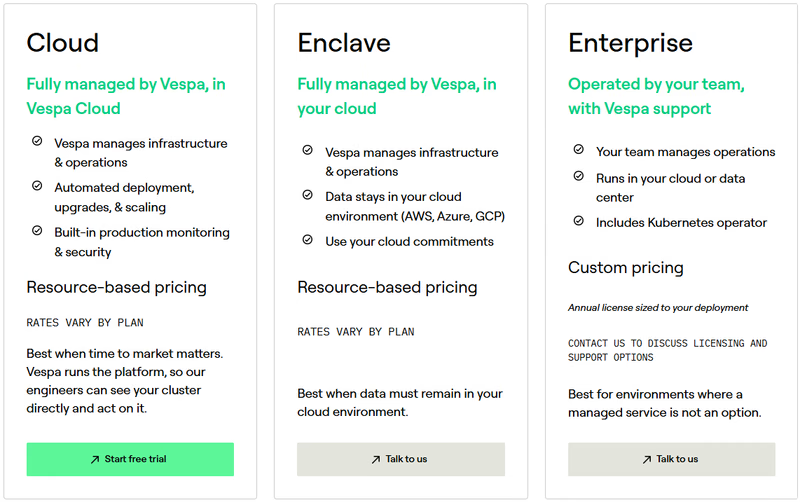
Vespa itself is open-source (Apache 2.0) and can be self-deployed at no software cost. They also offer Vespa Cloud, a managed service with usage-based pricing based on allocated resources (vCPU, memory, disk) per hour, with different tiers for support and features.
Pros and Cons
Vespa’s core advantage is search quality and scale. It will handle queries with dozens of conditions and millions of documents efficiently. Hybrid search and advanced ranking mean you can tightly control relevance.
However, running a Vespa cluster is more involved than a simple vector store. You must define a detailed schema and understand its query language. The managed cloud is based on raw resource pricing, which is hard to estimate. And because it’s a general search engine, it may be overkill if all you need is a simple vector KNN.
8. pgvector (postgres)
pgvector is an extension for PostgreSQL that adds vector similarity search to the classic SQL database. If your application already uses Postgres, you can keep everything in one database (data + vectors). You get full SQL querying power on the same data that backs your app.
Features
- Add a vector column type to Postgres. You insert embeddings as float arrays. pgvector implements HNSW and IVF indexes on these columns to accelerate similarity search.
- Join vector tables with relational tables and apply filters in the same SQL query to combine semantic and structured retrieval for RAG.
- Query nearest neighbors with standard SQL syntax and combine vector scores in broader SELECT statements.
- Use the extension, released under the permissive PostgreSQL License, on Postgres or compatible services like AWS Aurora and Supabase without requiring special hardware.
Pricing
pgvector is a free, open-source extension. Costs are associated with hosting the PostgreSQL database itself, which is available on all major cloud providers (like AWS RDS and Google Cloud SQL) with pay-as-you-go pricing.
Pros and Cons
The biggest pro is one-stop storage: your embeddings live alongside your application data. No need to sync between systems. You can leverage SQL, foreign keys, and complex filters naturally.
On the contrary, Postgres isn’t designed for massive vector workloads. Large embedding tables can slow down other DB operations. pgvector’s performance, while decent, lags behind specialized vector engines on high-dimensional data.
9. Elasticsearch
Elasticsearch (by Elastic) is a mature distributed search engine. Traditionally used for text, logs, and metrics, Elasticsearch can also store and search embeddings via its dense vector datatype.
Features
- Combine traditional BM25 keyword search with rich vector queries, add semantic retrieval with ELSER, and refine results with the Elastic Rerank model.
- Filter results on any field, including numeric ranges, geospatial, term, and aggregation queries, using the Query DSL to complement vector search.
- Scale horizontally by sharding indexes across nodes, and ensure production readiness with built-in replication and automated recovery.
- Integrate with a mature ecosystem including Kibana, Elastic APM, SIEM, and numerous connectors to manage, visualize, and ship data alongside vector search.
- Support cosine, dot-product, and L2 on dense vectors, using Lucene’s approximate k-NN for fast similarity.
Pricing
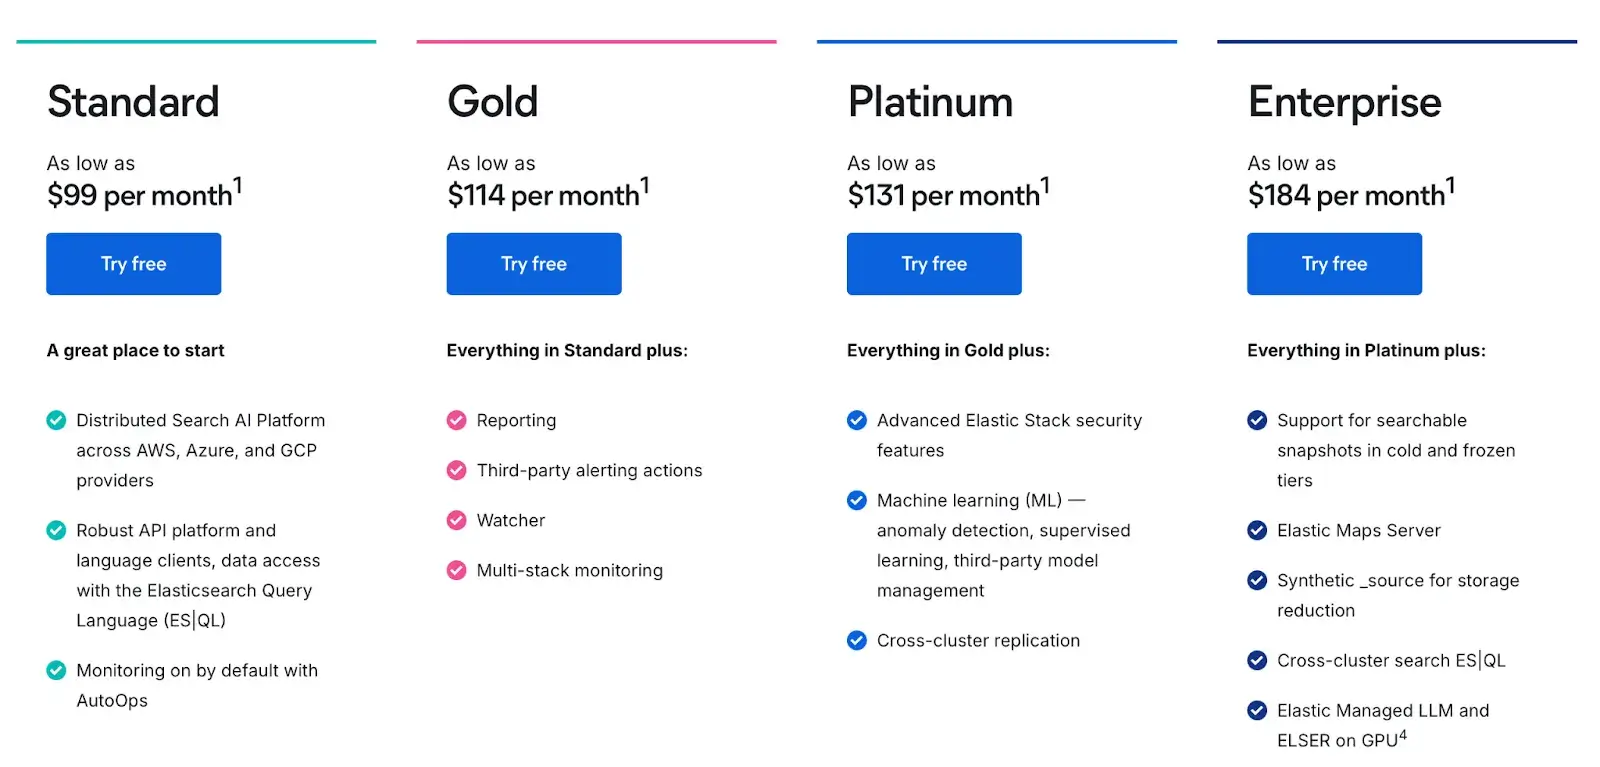
Elasticsearch is open-source, but the managed service is popular. On the Elastic Cloud Hosted plan, you have four paid tiers:
- Standard: $99 per month
- Gold: $114 per month
- Platinum: $131 per month
- Enterprise: $184 per month
Pros and Cons
Elasticsearch’s core strength for RAG is its mature and powerful hybrid search capability. If your organization already uses ES, adding vector search is straightforward; no new platform to learn. The recent Elasticsearch ML integrations, like semantic search, LLM-based ranking, and others, make it a natural choice for AI search.
However, it can be complex to manage and tune, and its resource consumption, especially memory, can be higher than that of some purpose-built vector databases. Historically, adding vectors to ES has had limitations, like slower indexing.
👀 Note: Elastic has improved it with quantized vector indexes (BBQ), which are now the default for vectors with 384 or more dimensions, but it can still be heavier than a specialized vector engine.
10. MongoDB
MongoDB, a leading document database, has integrated vector search directly into its platform with MongoDB Vector Search (formerly Atlas Vector Search). You store your data as usual in MongoDB collections and define a vector search index on a field containing embeddings. This allows developers to build RAG applications on a flexible document model, storing vectors alongside their application data.
Features
- Store embeddings alongside application data in MongoDB, add vector search to existing Atlas apps without migrations, and query with $vectorSearch while pre-filtering on any field you index as a filter.
- Combine full-text and vector results in a single pipeline with $rankFusion or $scoreFusion for hybrid relevance, and narrow the candidates with the filter option inside $vectorSearch, which must be the first stage of its pipeline.
- Process nearest neighbors with the aggregation pipeline to group, join, and project results, enriching RAG logic within one server-side query.
- Scale transparently through Atlas sharding and global distribution so vector search capacity grows with the underlying cluster.
- Use MongoDB Vector Search on Atlas at no additional charge, pay only for the cluster, and prototype on the free M0 tier with small size limits.
Pricing
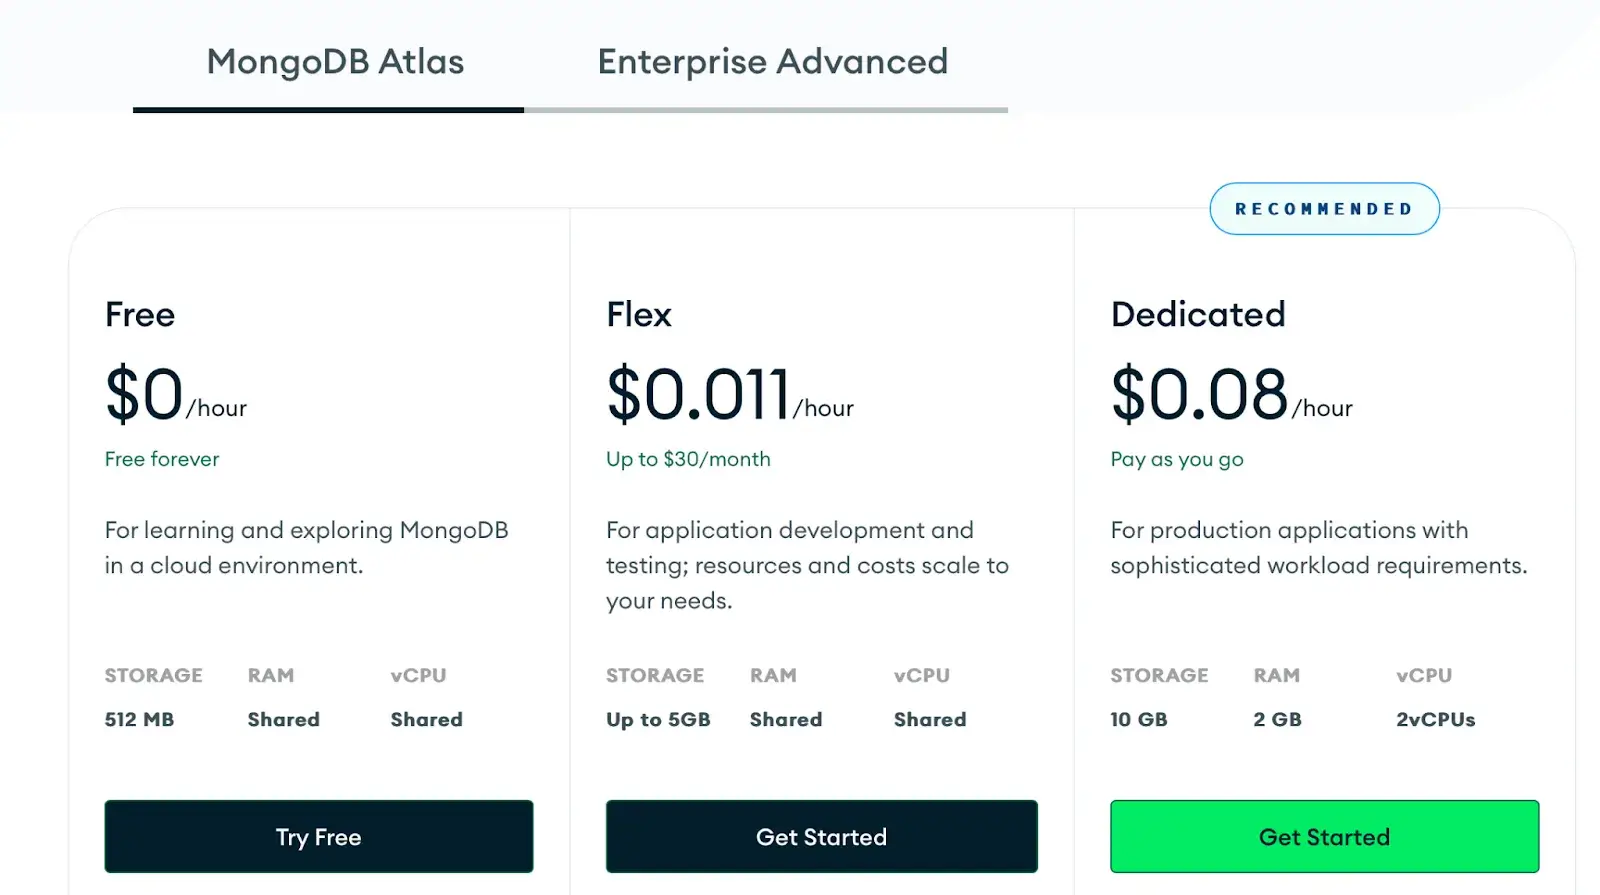
Vector Search in Atlas has no separate fee. It’s included on all cluster tiers. You only pay for the normal MongoDB cluster cost, which is as follows:
- Free (Up to 512 MB storage, shared RAM, and vCPU)
- Flex: Up to $30 per month ($0.011 per hour)
- Dedicated: Pay as you go ($0.08 per hour)
Pros and Cons
If your application already uses MongoDB, vector search just fits without moving data. Its flexible document model and rich query language are also major benefits.. Also, the zero additional cost for the vector feature is a big advantage for smaller projects or prototypes.
As a more recent addition, its large-scale vector workloads are improving but may lag dedicated systems. The feature set is still evolving; you can now tune HNSW options and quantization, but the choice of index types is narrower than in dedicated vector databases.
Which Vector Database for RAG Pipelines is the Best in Business?
Choosing the right vector database depends on your priorities. What do you prioritize: latency, scalability, cost efficiency, or ecosystem fit? Each of the databases we tested brings its own strengths and trade-offs to the table. The honest answer is that the best one is the one that wins on your documents and your queries, and you only find that out by testing.
That’s where ZenML comes in.
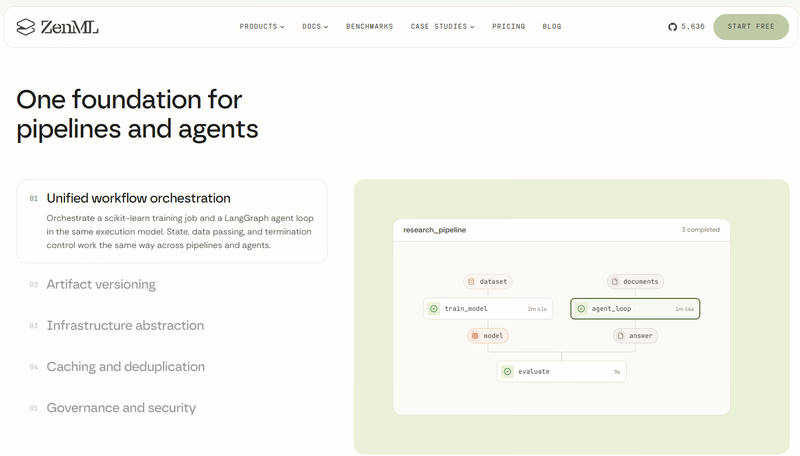
ZenML is not a vector database; it’s the orchestration layer for your entire RAG and agent pipeline. You write ingestion, embedding, indexing, and retrieval evaluation as steps in a Python pipeline, using each database’s own client, and ZenML versions the output of every step. It also caches steps whose inputs haven’t changed, so you embed your documents once and load the same vectors into Pinecone, Qdrant, or Postgres with pgvector without paying for embeddings again.
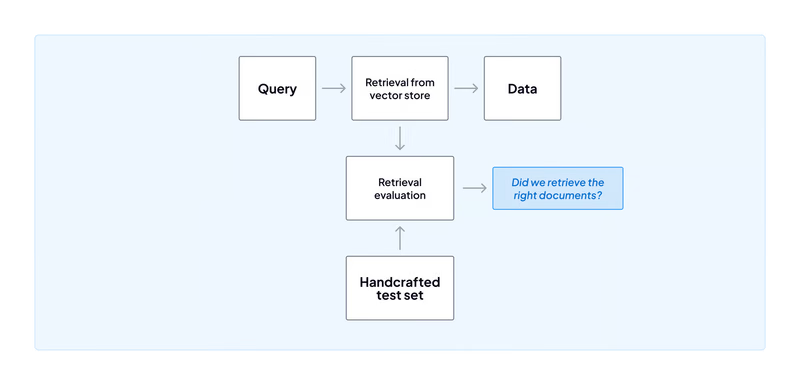
The comparison itself is a pipeline too. Fan out one step per database or per index setting, like HNSW’s M and ef_construction, run the same test queries against each, and log the retrieval failure rate and query latency as metadata on the run. Every trial is tracked and reproducible, so “which database is best” becomes a result you can re-run as your data grows, not a guess you made once.
The pipeline keeps earning its place after you choose. When you change your chunking or fine-tune your embeddings, you re-run it to rebuild the index and check that retrieval didn’t get worse.
Bottom line: The best vector database is the one that wins on your data, and ZenML is how you run that test and keep running it.
Wrapping Up: Our Top Vector Database Picks
Among all the options we tested, a few consistently stood out for different reasons.
Pinecone remains the go-to choice for teams that want a fully managed, serverless database with real-time indexing and enterprise reliability. If you value ease of use and don’t want to worry about infrastructure, Pinecone delivers a production-ready experience straight out of the box.
For teams looking for an open-source solution with strong performance and advanced metadata filtering, Qdrant is hard to beat. It brings the speed of Rust together with flexible deployment, making it ideal for complex RAG pipelines.
Another favorite is Weaviate, an AI-native database with built-in vectorization and multimodal support, which is particularly appealing for developers who want to experiment with hybrid and multimodal search in one system.
And if your workload demands extreme scale and GPU acceleration, Milvus is a proven enterprise option capable of handling billions of vectors with ease.
If you’re interested in taking your AI agent projects to the next level, start with open-source ZenML. It orchestrates pipelines and agents in Python on the infrastructure you already run, and ships integration examples for 12 agent frameworks (like LangGraph, CrewAI, and more).
With ZenML, you can seamlessly integrate whichever vector database and agent framework you choose into robust, production-grade workflows.
Install it with one command: curl -fsSL https://zenml.io/install-zenml | bash, or start free on ZenML Pro with a 14-day trial and no credit card.
- AI engineers on your agent
- Set up in minutes
- No credit card