On this page
Databricks combines data engineering, SQL analytics, machine learning, and governance in one platform. The right alternative depends on which of those capabilities your team needs to replace.
This guide compares 10 options for different workloads: Python ML orchestration, managed SQL analytics, open-source Spark processing, and governed enterprise data platforms. Microsoft Fabric replaces the broad Microsoft Azure entry, while the Google and Oracle sections identify their current, more specific offerings.
Start with workload fit, deployment requirements, and total operating cost. A pipeline framework, a SQL warehouse, and a managed Spark service cover different parts of a Databricks deployment.
Databricks Alternatives Quick Overview
- Why compare alternatives: Match your processing engine, governance needs, deployment model, and budget to the workload you actually run.
- Choose by workload: Consider ZenML for Python ML pipelines; Fabric, Snowflake, Redshift, BigQuery, or Oracle Autonomous AI Lakehouse for SQL and analytics; and Spark, EMR, or Google Cloud Managed Service for Apache Spark for Spark workloads. Cloudera suits teams evaluating a hybrid data platform.
- Compare total cost: Include compute, storage, data transfer, licenses, operations, and migration. None of these ten options is automatically cheaper or a complete replacement for every Databricks service.
Recently Updated (September 2026): Updated the tool comparison, Microsoft Fabric, Google Cloud Managed Service for Apache Spark, and Oracle Autonomous AI Lakehouse coverage, along with selected feature descriptions and images.
The Need For Databricks Alternatives
There are several reasons why you might need an alternative to Databricks:
- Not beginner-friendly software
- Poor documentation and release notes
- Lack of excellent customer support
Here are the two main reasons worth discussing.
Reason 1. Overwhelming For Beginners
If you’re a beginner with no experience in SQL and Spark, you will have a hard time wrapping your head around Databricks.
Nowadays, many tools work as well as Databricks, where you can simply drag and drop commands rather than writing SQL queries.

Reason 2. New Updates Take Time to Understand
Databricks frequently updates its platform, which is great, but it often fails to update its documentation as frequently as needed.
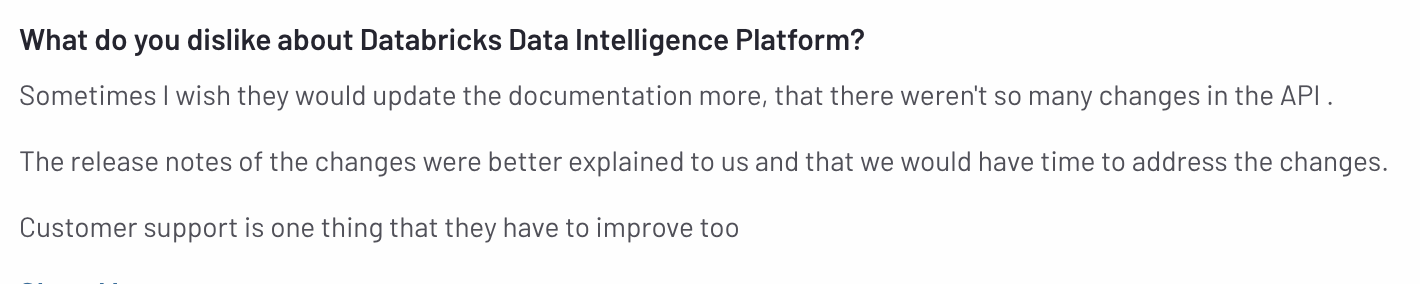
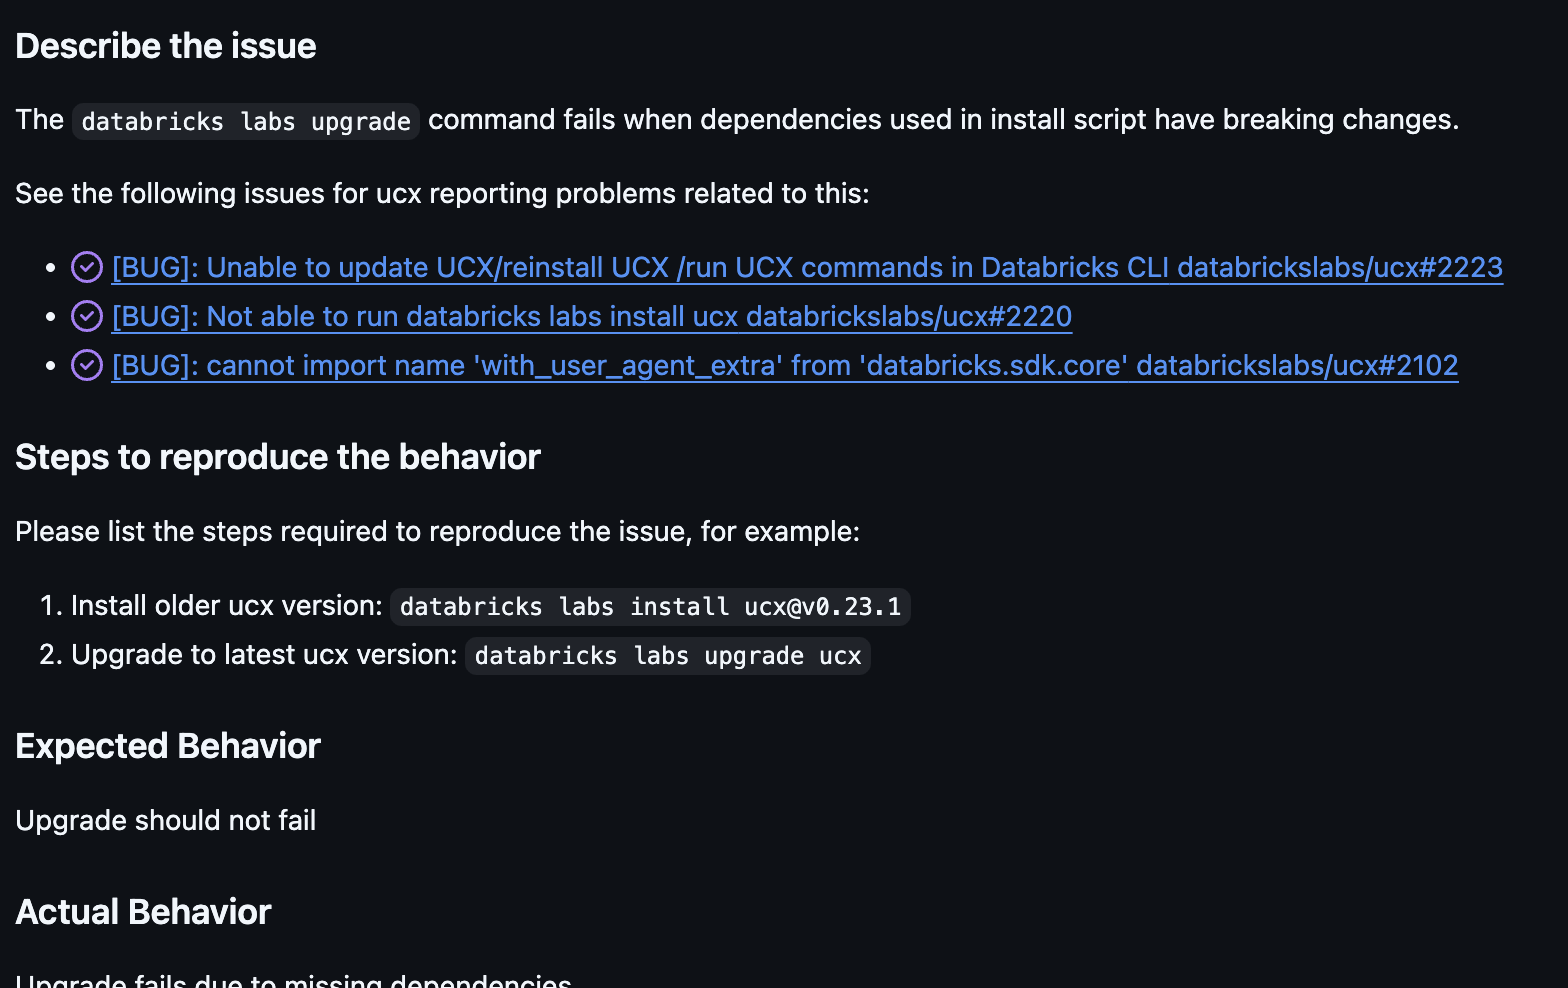
What’s more, the release notes also don’t do a great job of explaining new updates comprehensively. Additionally, the upgrades often fail to install due to bugs.
Evaluation Criteria
This comparison uses vendor documentation and pricing pages reviewed on September 22, 2026. It is not a performance benchmark.
1. Workload and Development Experience
Identify whether the priority is SQL analytics, distributed Spark processing, Python ML pipelines, or a broader data platform. Compare the languages, APIs, and operational skills required for that workload.
2. Deployment and Governance
Check supported clouds, self-hosting options, access controls, lineage, and data residency. Open table formats can improve interoperability, but they do not automatically make jobs, permissions, or platform APIs portable.
3. Total Cost and Migration Effort
Include compute, storage, data movement, licenses, and the work of operating and migrating the system. Test candidates with the same data, concurrency, and service requirements before making performance or savings claims.
With these criteria in mind, compare the ten alternatives below.
What are the Best Databricks Alternatives and Competitors?
Some of the best alternatives to Databricks are:
| Alternative | Capabilities | Best fit |
|---|---|---|
| ZenML | Python pipelines, artifacts, and configurable infrastructure stacks | ML teams choosing orchestration across supported compute and storage |
| Microsoft Fabric | OneLake, Spark, SQL, Real-Time Intelligence, and Power BI | Microsoft teams connecting data engineering with BI |
| Snowflake | SQL analytics, Snowpark, Cortex AI, and Iceberg tables | Warehouse-centered analytics and data processing |
| Amazon Redshift | Provisioned or Serverless SQL; warehouse and Iceberg queries | AWS teams prioritizing SQL analytics |
| Apache Spark | Distributed batch processing, MLlib, and Structured Streaming | Teams needing runtime control and able to operate the surrounding stack |
| Google BigQuery | Managed SQL and ML, streaming ingestion, and Iceberg tables | SQL analytics with managed infrastructure and open-table access |
| Amazon EMR | Open-source engines on EC2/EKS; Spark and Hive with Serverless | AWS teams choosing configurable clusters or managed Spark jobs |
| Cloudera | Hybrid data services, governed Iceberg, and AI development and serving | Organizations with data residency and hybrid infrastructure requirements |
| Google Cloud Managed Service for Apache Spark (formerly Dataproc) | Managed clusters or serverless Spark, with configurable runtimes | Google Cloud teams retaining Spark workloads |
| Oracle Autonomous AI Lakehouse | Managed Oracle analytics, Iceberg access, and in-database AI | Oracle-oriented teams evaluating a managed analytics lakehouse |
Quick Selection Guide by Use Case:
- Rapid ML prototyping → production: ZenML lets you develop locally and deploy to any cloud
- Heavy SQL analytics with minimal ops: Snowflake or BigQuery
- Real-time streaming at scale: Apache Spark on EMR or Dataproc
- Hybrid cloud with strict governance: Cloudera
- AWS-native data warehousing: Redshift with AQUA
1. ZenML
ZenML is a Python framework for defining ML pipelines and tracking their runs and artifacts across configurable infrastructure stacks. It is useful when the part of Databricks you need to replace is ML workflow orchestration.
ZenML does not provide a SQL warehouse or a distributed data-processing engine. You connect it to the compute, storage, and tracking tools that your workflow needs, which can include Databricks itself.
Feature 1. Simplified Pipeline Development with Production-Ready Outcomes
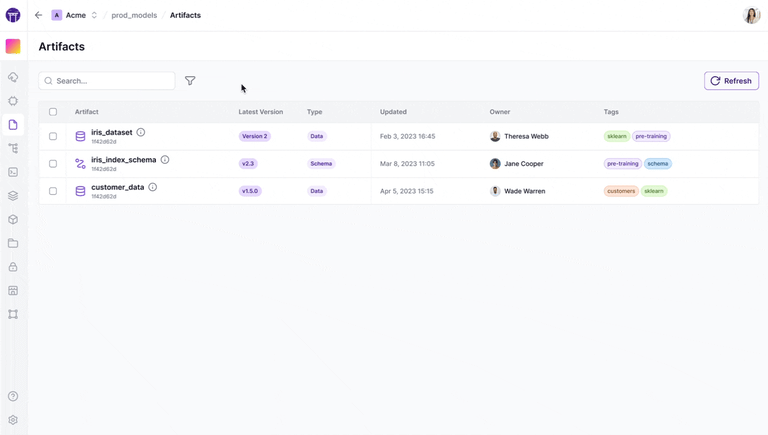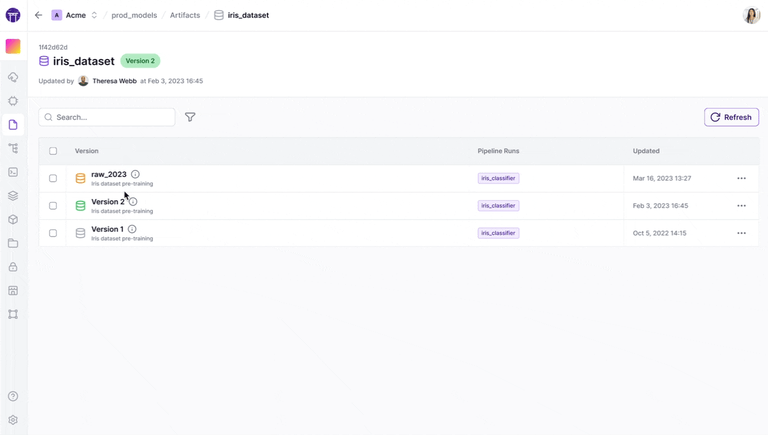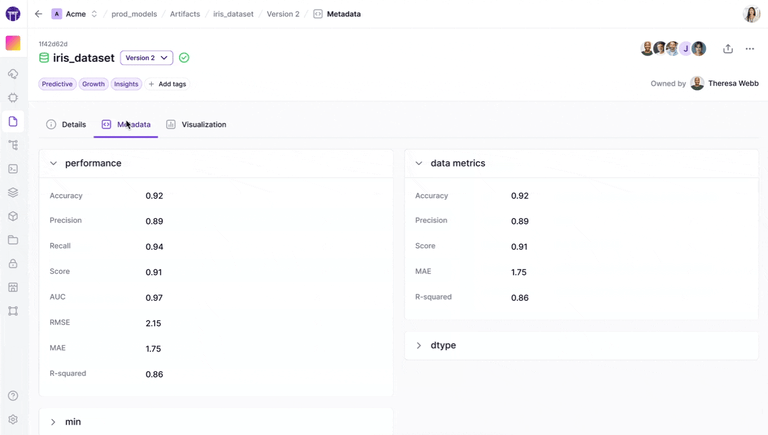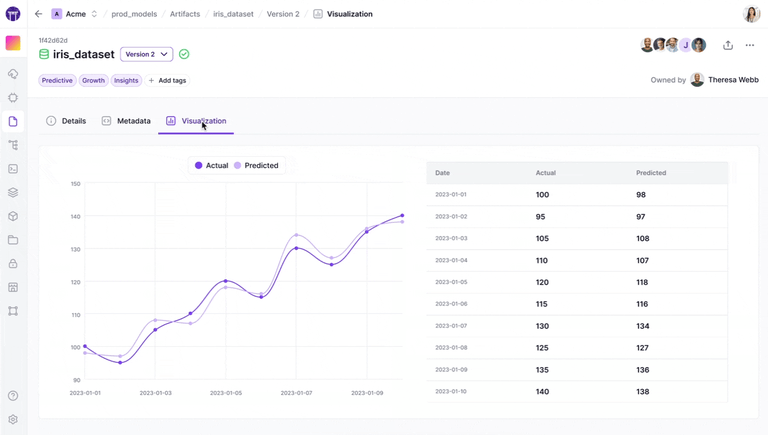
ZenML turns Python functions into pipeline steps using decorators. Databricks also supports Python scripts and wheels, so the distinction is how workflows and infrastructure are organized, rather than whether Python code is supported.
This lets ML practitioners use familiar Pythonic workflows while automatically gaining critical MLOps capabilities like:
- Python steps: Define typed functions with
@stepand connect them in a@pipelinefunction. - Configurable infrastructure: Select supported orchestrators, artifact stores, and other components through a stack. Remote execution still requires the appropriate credentials, dependencies, and infrastructure.
- Caching: Reuse outputs when the configured cache key matches, including step code, parameters, and input artifacts. Changes in external files or APIs are not automatically detected; disable caching or add explicit dependencies where needed.
This design philosophy eliminates much of the “negative engineering” that plagues ML productionization efforts, reducing the gap between prototype and production code.
Here is a minimal ZenML Pipeline. It illustrates step dependencies and artifact tracking, rather than comparing performance with a Spark training job.
from zenml import pipeline, step

@step
def ingest() -> list[float]:
    return [1.0, 2.0, 3.0]

@step
def calculate_mean(values: list[float]) -> float:
    return sum(values) / len(values)

@pipeline
def example_pipeline():
    calculate_mean(ingest())

if __name__ == "__main__":
    example_pipeline()
Feature 2. Artifact Versioning and Metadata
ZenML stores step outputs as artifacts and tracks the runs, steps, and inputs associated with them. This helps trace a result back through a pipeline.
- Artifact versioning: Access named artifacts and their versions across runs.
- Metadata: Supported materializers extract properties such as a pandas DataFrame’s shape and size. Log task-specific metrics explicitly or through the relevant integration.
- Reproducibility: Preserve data, dependencies, configuration, and external state as well as pipeline metadata. Artifact tracking alone does not guarantee an identical rerun.
Feature 3. The Model Control Plane: A Unified Model Management Approach
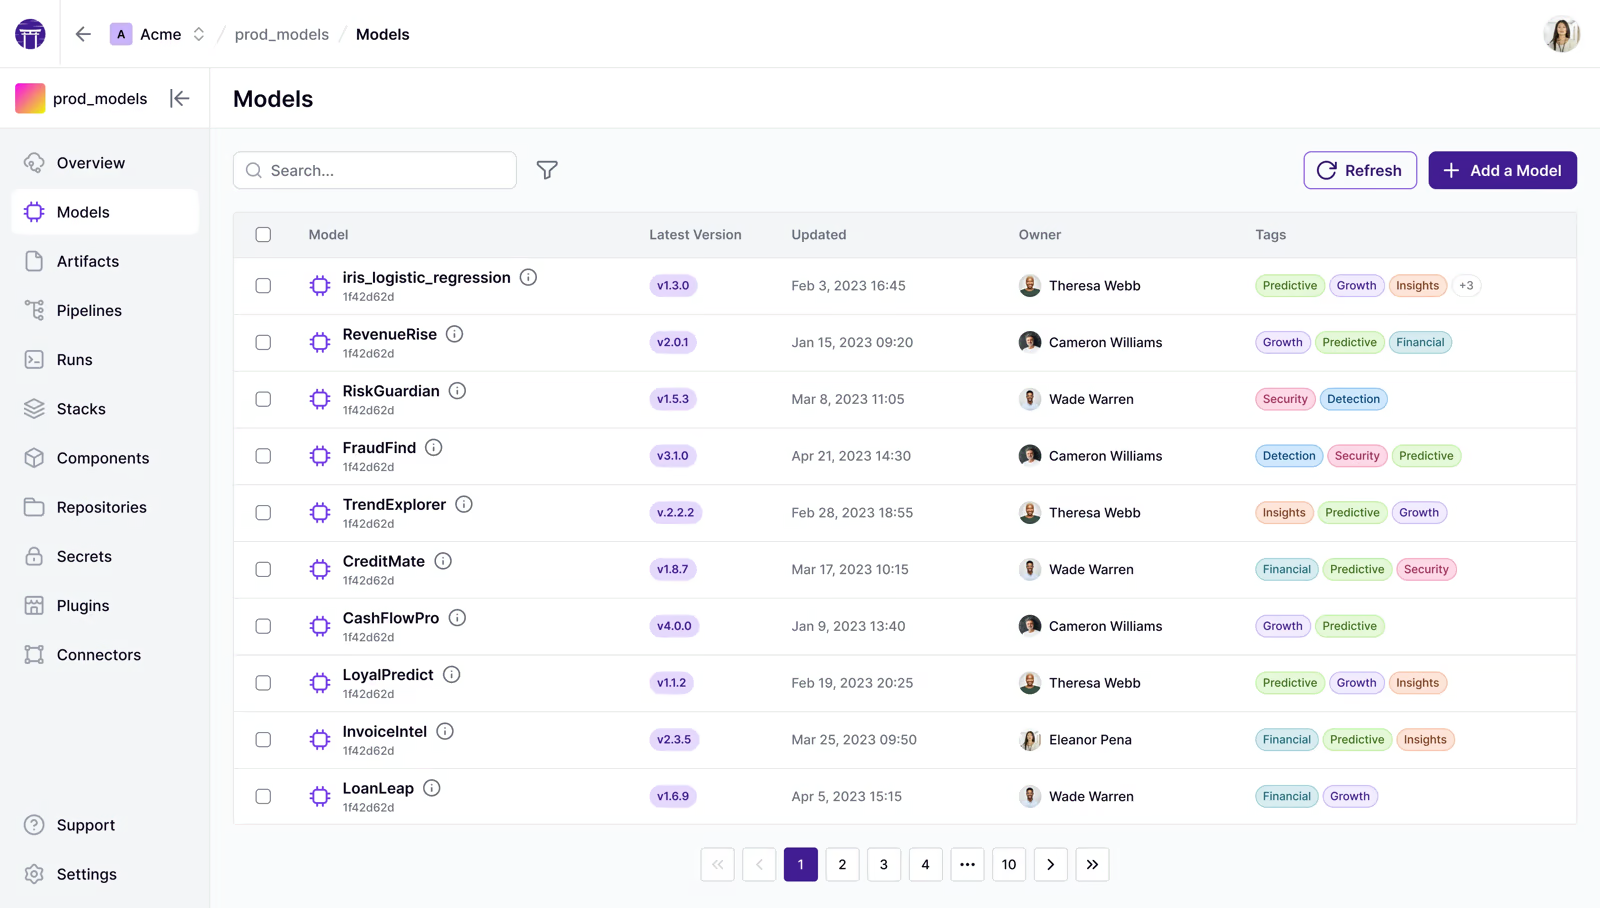
ZenML’s Model Control Plane represents a significant advancement over Databricks’ model management approach.
Databricks provides an MLflow Model Registry (and now Unity Catalog for models) to version models, but ZenML goes further by unifying pipeline lineage, artifacts, and business context into a single model-centric framework.
With ZenML’s Model Control Plane:
- Business-oriented model concept: A ZenML Model is a first-class entity that groups the relevant pipelines, artifacts, metadata, and business metrics for a given ML problem.
- Lifecycle management: Models in ZenML have versioning and stage management built in. Each training run can produce a new Model Version, tracked automatically with lineage to the data and code that created it.
- Artifact linking: The Model Control Plane allows linking each model version to not only its technical artifacts (weights, metrics) but also to relevant non-technical context.
How Does ZenML Compare to Databricks?
ZenML separates pipeline definitions from supported infrastructure components. You can develop with a local stack and configure a remote stack for production, while checking dependencies, credentials, and backend-specific settings.
You can also keep Databricks as a backend. ZenML documents a Databricks orchestrator and a Databricks step operator for selected steps. It also lists a Spark-on-Kubernetes step operator; that operator does not support dynamic pipelines in the current compatibility table.
Databricks supports local IDE development through Databricks Connect, with Spark operations executing remotely. Its serverless jobs manage compute resources for supported task types, so users do not manually provision a cluster for each job.
Pros and Cons
ZenML is a fit for teams that want Python pipelines and artifact tracking across their chosen infrastructure. The open-source framework is free to self-host; infrastructure and operations still cost money. Pro adds paid control-plane capabilities.
The trade-off is responsibility for the surrounding stack. ZenML does not replace the warehouse, processing engine, identity policies, or serving infrastructure that a complete Databricks deployment may use.
2. Microsoft Fabric
Microsoft Fabric brings data integration, Spark engineering, SQL warehousing, data science, real-time analytics, and Power BI into one SaaS platform. It is worth evaluating when Microsoft-based teams want to connect data preparation with business reporting.
Features
- Shared data: OneLake supplies a common data lake. Shortcuts let workloads access supported external storage, including Amazon S3 and Azure Data Lake Storage, without first copying that data into Fabric.
- Multiple processing engines: Data Factory handles ingestion and orchestration, Spark notebooks support engineering, and the warehouse provides SQL analytics. Real-Time Intelligence handles event data.
- ML and reporting: Fabric supports MLflow model management and batch scoring, with Power BI for downstream reporting.
Pros and Cons
Microsoft Fabric brings data engineering, data warehousing, data science, real-time analytics, and Power BI into one SaaS platform. This reduces the need to stitch together multiple Azure services and gives teams a more consistent environment for building end-to-end data and analytics workflows.
Cost and capacity management can become difficult to predict. Fabric uses shared Capacity Units across workloads, so Power BI, Spark, warehouses, and other services can compete for the same capacity.
3. Snowflake
Snowflake combines managed SQL analytics with data engineering and AI. Consider it when warehouse data and SQL workflows anchor your analytics stack.
Features
- Storage and compute scale independently. SQL handles formats including JSON and XML; Snowpark supplies Python, Java, and Scala APIs.
- Time Travel provides historical queries within configured retention. Standard-table clones initially share storage; later changes can add storage charges.
- Snowflake supports staged files. Cortex AI Functions add classification and document parsing. Region support and GA or preview status vary by function.
- Iceberg tables support Snowflake or external catalogs, with different platform features and maintenance responsibilities.
Pros and Cons
Snowflake lets you restore and edit older data versions and comes with the ability to manage massive datasets, straightforward queries, and fast performance.
However, the platform primarily focuses on structured and semi-structured data, lacking robust native support for unstructured data types.
4. Amazon Redshift
Amazon Redshift is a managed SQL data warehouse for teams working in AWS. It offers provisioned clusters and Redshift Serverless, which adjusts compute capacity to workload demand.
Features
- Columnar storage and parallel query execution support large SQL analytics workloads.
- Redshift queries Iceberg tables registered in AWS Glue and joins lake data with warehouse tables. Supported formats, permissions, and catalog setup still matter. Iceberg support.
- SUPER columns support semi-structured data; COPY can load JSON and nested Parquet or ORC. Ingestion documentation.
- Redshift ML uses SageMaker AI for supported training workflows and exposes predictions through SQL. It does not replace every custom model-training or serving workflow. Redshift ML.
Pros and Cons
Redshift integrates well with other AWS services, which makes it easy to implement and scale. The tool’s architecture allows for easy scaling to accommodate growing data volumes and user concurrency.
One negative aspect we observed with Redshift is that it can be expensive to process on a large scale, particularly with increasing amounts of data.
5. Apache Spark
Apache Spark is an open-source, distributed computing system designed for large-scale data processing.
It provides a unified engine capable of handling batch processing, real-time streaming, machine learning, and graph analytics.
Features
- By processing data in memory, Spark significantly reduces the time required for data retrieval and computation, resulting in faster analytics compared to traditional disk-based processing systems.
- It supports APIs in Java, Scala, Python, and R. Developers can build applications in the language they know best, which helps teams collaborate more efficiently across different stacks.
- Includes built-in libraries such as MLlib for machine learning, GraphX for graph processing, and Spark Streaming for real-time data processing. These built-in tools cover most analytical use cases without needing third-party add-ons.
- Designed to scale from a single server to thousands of machines, Spark can handle petabyte-scale data, making it suitable for both small-scale applications and large enterprise solutions.
Pros and Cons
With Apache Spark, you can handle large volumes of data, making it horizontally scalable. What’s more, its fault tolerance through data replication and support for batch streaming makes data processing faster.
However, the platform lacks built-in support for event time processing.
6. Google BigQuery
Google BigQuery is a fully managed, serverless data warehouse that enables scalable analysis over petabyte-scale data.
Its architecture decouples storage and compute, allowing for flexible resource allocation.
Features
- Google BigQuery removes the need for manual infrastructure setup. It automatically provisions and scales resources based on workload demands.
- You can build and run machine learning models using standard SQL inside BigQuery. This feature supports predictive analytics without moving data into separate ML environments.
- Supports real-time data ingestion, allowing teams to analyze fresh data as it arrives, making it ideal for operational dashboards and streaming use cases that would otherwise require Databricks Structured Streaming.
- It allows cross-source querying across Cloud Storage, Google Drive, and external databases. Teams can analyze distributed data without replicating or transferring it to a central warehouse.
Pros and Cons
BigQuery makes working with large datasets easy and offers several user-friendly learning tutorials, as well as a reliable community to help solve all your problems.
However, remember that if you're not careful, complex queries for large datasets can add up, resulting in a significant increase in pricing.
7. Amazon EMR
Amazon EMR runs open-source data-processing frameworks on AWS. Choose among EMR on EC2, EMR on EKS, and EMR Serverless according to the infrastructure control your jobs need.
Features
- Supports multiple open-source engines such as Apache Spark, Hadoop, Hive, and Presto. This flexibility allows teams to choose the right tool for their specific data processing needs, unlike Databricks, which primarily centers on Spark.
- EMR clusters can scale compute power up or down depending on demand. This elasticity helps teams manage large workloads without overprovisioning resources.
- Teams can customize EMR cluster configurations to match application-specific requirements, making it an appealing tool for engineers who want deeper tuning than what Databricks’ managed environment allows.
- Auto Scaling and Spot Instance support reduces compute costs, especially for long-running or batch workloads.
Pros and Cons
Amazon EMR makes it easy for you to launch and clone an EMR cluster. The platform seamlessly connects to S3, Glue, and Lake Formation for data storage, cataloging, and governance.
But one issue we ran into: booting up takes more time compared to other competitors in the space.
8. Cloudera
Cloudera provides data engineering, analytics, and AI services for public-cloud and on-premises environments. It is worth evaluating when data residency or existing infrastructure makes a cloud-only platform unsuitable.
Features
- Supports deployment across public cloud, private cloud, and on-premise environments, giving you more control over data residency and infrastructure.
- Combines ingestion, storage, processing, and analytics into a single integrated platform. Teams can build complex data workflows without relying on separate services for ETL, data warehousing, or business intelligence.
- The platform features include data governance, lineage tracking, and regulatory compliance, which are particularly useful in highly regulated industries.
- Provides tools for developing and deploying machine learning models using open-source frameworks. It supports building end-to-end ML workflows similar to what Databricks offers with MLflow and collaborative notebooks.
Pros and Cons
Cloudera’s Hadoop distribution enhances enterprise Hadoop with built-in security, scalability, and management tools, and it has a large and active community of users and developers.
But the learning curve for the tool is quite steep. You need expertise to manage on-prem HDFS clusters and optimize performance.
9. Google Cloud Managed Service for Apache Spark (formerly Dataproc)
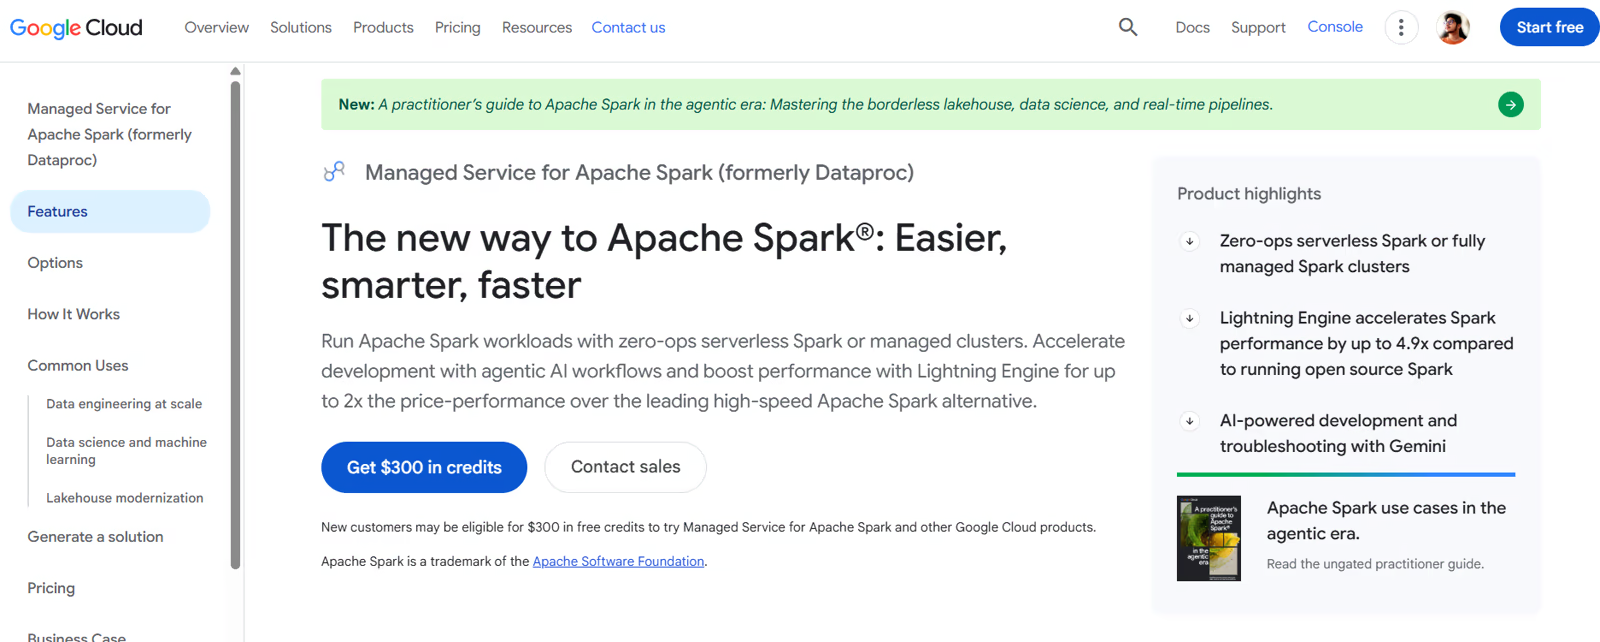
Google Cloud Managed Service for Apache Spark, formerly Dataproc, combines managed clusters and serverless Spark execution. It is a natural candidate for Google Cloud teams moving Spark workloads while keeping the Spark programming model.
Features
- Use serverless execution for Spark batch jobs and interactive sessions without provisioning a cluster. Choose managed clusters when you need persistent environments, infrastructure customization, or other supported open-source components.
- Connect Spark workloads to Cloud Storage and BigQuery. Check connector and API charges alongside compute costs.
- Customize cluster software and configuration, or supply supported custom containers for serverless workloads. Managed clusters also support autoscaling and Spot VMs for suitable fault-tolerant workloads.
- Lightning Engine adds vectorized query execution on supported runtimes. Serverless uses the Premium tier, while clusters have a separate add-on charge. Check runtime compatibility before budgeting around it.
Pros and Cons
The two deployment modes let teams choose between less infrastructure management and greater control. Both still require attention to job design, dependencies, permissions, and data access. Serverless can run Spark streaming libraries, but Google states that checkpointing and restarts remain your responsibility.
10. Oracle Autonomous AI Lakehouse
Oracle Autonomous AI Lakehouse combines Oracle’s managed analytical database with Apache Iceberg access. It is a more focused Databricks alternative than the broad Oracle Database product family, particularly for teams with Oracle SQL workloads or existing Oracle data.
Features
- Query Iceberg data and integrate with supported catalogs, including Databricks Unity Catalog, AWS Glue, and Snowflake Polaris. This provides an interoperability path when data spans several analytics platforms.
- Use SQL analytics, in-database machine learning, AI Vector Search, and Select AI for supported analytical and AI workloads.
- Automate database administration tasks such as provisioning, patching, backups, and tuning. Workload design, access policies, and cost management still require team decisions.
- Choose supported deployments on OCI, AWS, Azure, Google Cloud, or Exadata Cloud@Customer. The on-premises option uses Oracle’s Exadata Cloud@Customer service; it is not a generic installation on any private server.
Pros and Cons
This is a useful shortlist option when Oracle SQL skills, managed database operations, and access to Iceberg data matter more than retaining a Spark-centric development environment. Existing Spark jobs and Databricks-specific pipelines still need a migration assessment.
Deployment options and licensing affect the bill. Dedicated infrastructure and Cloud@Customer have different infrastructure commitments from the serverless service, so compare the exact offering you intend to run.
Choosing the Right Alternative
Start with the capability you need to replace. ZenML addresses Python ML orchestration; Fabric connects engineering and BI; Snowflake, BigQuery, Redshift, and Oracle Autonomous AI Lakehouse address SQL and analytics use cases. Spark, EMR, and Google Cloud Managed Service for Apache Spark retain Spark-based processing, while Cloudera offers a hybrid data platform.
Check the data formats, catalogs, permissions, job definitions, model artifacts, and endpoints your team depends on. Shared SQL, Python, or Iceberg support can help, but it does not make platform APIs or governance policies interchangeable.
Which Databricks Alternative Fits Your Team?
Shortlist two or three tools for one representative workload. Compare functionality, operating effort, and the full bill using the same data, concurrency, reliability, and security requirements.
Databricks remains worth evaluating when its combined engineering, analytics, ML, and governance capabilities match your needs. Moving only the orchestration layer can be a smaller change than replacing the entire platform.
If Python ML pipelines are your priority, book a ZenML demo to discuss the infrastructure and workflow you want to support.
Related reading:
- MLflow alternatives: Compare options for experiment tracking and model workflows.
- Metaflow alternatives: Explore other approaches to Python ML workflows.
Common Questions About Databricks Alternatives
Is Databricks still worth it in 2025? Databricks remains powerful for teams with deep Spark expertise and heavy big data processing needs. However, many ML teams find that lighter-weight orchestration tools like ZenML, combined with managed compute from cloud providers, deliver better developer experience and lower costs for typical ML workflows.
What's the most cost-effective alternative to Databricks? Cost depends heavily on your workload. For SQL analytics, Snowflake or BigQuery often prove cheaper. For ML orchestration, open-source frameworks like ZenML with your existing cloud infrastructure typically cost 50-70% less than Databricks Unity Catalog setups.
Can I migrate from Databricks without rewriting everything? Yes. Tools like ZenML let you keep your Python code largely intact while changing the underlying orchestration. The key is choosing a vendor-agnostic framework that doesn't lock you into specific APIs or data formats.