On this page
DeepEval has become the go-to evaluation framework for many ML engineers testing LLM applications. Its Python-first approach and pre-built evaluation metrics make it appealing to many.
But as evaluation workflows scale, you hit limitations: heavy reliance on LLM-as-a-judge scoring, rising inference costs, or integration friction with non-Python ecosystems.
- AI engineers on your agent
- Set up in minutes
- No credit card
In this article, we survey the 8 best open-source LLM evaluation frameworks that serve as alternatives to DeepEval. We briefly discuss why you need an alternative, outline key criteria for choosing an eval framework, and then dive into the top tools available.
TL;DR
- Why Look for Alternatives: DeepEval's heavy reliance on LLM-as-a-judge scoring is expensive and slow. It doesn’t cover every scenario, like custom rule-based checks or integration with your data. DeepEval alternatives offer more cost-efficient, flexible, or transparent evaluation methods beyond AI judges.
- Who Should Care: ML engineers and Python developers building production LLM applications who need efficient evaluation frameworks with flexible metrics, cost transparency, and better integration with observability layers.
- What to Expect: We evaluate each alternative on cost efficiency, metric philosophy (judges, rules, or both), coverage of use cases (RAG, agents, safety), and data governance. Each framework handles single and multi-turn evaluations differently.
The Need for a DeepEval Alternative?
1. Heavy Reliance on LLM-as-a-judge
DeepEval leans almost entirely on using AI models to grade other AI models. In fact, nearly all metrics in DeepEval are LLM-as-a-judge.
At a time when LLMs are known to confidently produce plausible-sounding but entirely fabricated or incorrect information, using AI to judge another AI messes up the equation.
That’s why teams are shifting from DeepEval toward hybrid AI systems, emphasizing ‘human-in-the-loop’ processes. Human judgments remain costly and slow, though more reliable and accurate.
2. Cost and Latency of Large-Scale Evals
Using GPT-5 or similar large models as evaluation judges is not cheap. Each test case performs another LLM inference, compounding costs dramatically when you have hundreds or thousands of cases.
This means running a massive evaluation suite with DeepEval racks up significant API bills and also slows down CI pipelines due to the latency of model calls.
Many alternatives aim to reduce this by offering lighter-weight metrics (like embedding-based similarity or regex checks) or by allowing the use of smaller local models as judges to cut costs.
3. Python-First Ecosystem and Integration Friction
DeepEval’s design is inspired by unit testing (with Pytest integration) and comes with a companion cloud platform (Confident AI).
But fitting it into an existing MLOps toolchain requires extra effort. In short, if DeepEval doesn’t play nicely with your environment, an alternative with a more flexible or lightweight integration saves a lot of headaches.
Evaluation Criteria
Not all evaluation frameworks are built the same. Here are the key criteria to consider as you evaluate DeepEval alternatives:
- Associated costs: What is the true cost of ownership at scale? Understanding pricing models helps determine feasibility for large-scale deployments.
- Coverage of your use cases: Does the tool evaluate RAG, agents, chatbots, safety concerns, and more? Different frameworks excel in different domains, so matching coverage to your architecture is critical.
- Metric philosophy: Does the alternative offer judges, rules, or both? A balanced approach reduces costs while maintaining evaluation flexibility.
- Data, privacy, open source, and governance: Is it open-source? Can you self-host? Teams with compliance requirements need on-premise options and clear data handling practices.
What are the Top Alternatives to DeepEval?
Here’s a quick table comparing all the top DeepEval alternatives we’re going to talk about next:
| DeepEval Alternatives | Best For | Key Features | Pricing |
|---|---|---|---|
| Kitaru by ZenML Labs | Teams that want to run their evals, DeepEval metrics included, on real agent traces and test a fix before it ships. | - Runs your own evaluators on imported traces - Deterministic checks with no model calls - Replays a fix against failed sessions | - Open-source - ZenML Pro starts at $39 per month |
| Ragas | RAG-specific evaluation with deep semantic metrics. | - Faithfulness and relevance scoring - Synthetic test generation - Hybrid evaluators | Free (Open-source) |
| TruLens | Trace-first evals with LLM feedback and integration with LangChain. | - Token-level trace logging - Built-in evals like groundedness - LLM feedback functions | Free (Open-source) |
| Promptfoo | Fast, repeatable prompt testing and CI integration. | - CLI + CI testing - Prompt performance tracking - Failure logs and metadata | Free (Open-source) |
| Arize Phoenix | Notebook-first debugging and RAG evals with OpenTelemetry. | - Local trace execution - LLM and metric-based evals - Cost-aware RAG tuning | - Open-source - Paid plan starts at $50 per month |
| Langfuse | Full-stack LLM observability with prompt control and evals. | - Nested trace trees - Prompt versioning - Live latency/cost dashboards | - Open-source - Paid plans start at $29 per month |
| Evidently | Hybrid evals and monitoring for quality, safety, and drift. | - 100+ built-in metrics (rules, classifiers, LLM judges) - Data drift detection - Synthetic and adversarial test data | Free (Open-source) |
| LangSmith | LangChain-native apps needing hosted trace + eval infra. | - Prompt + chain versioning - LLM/human/rule feedback - Visual debug tools | - Free - Paid plans start at $39 per month |
1. Kitaru by ZenML Labs
Best for: Teams that want to run their evals, DeepEval metrics included, on the traces their LLM app or agent already produced, and test a fix against real sessions before it ships.
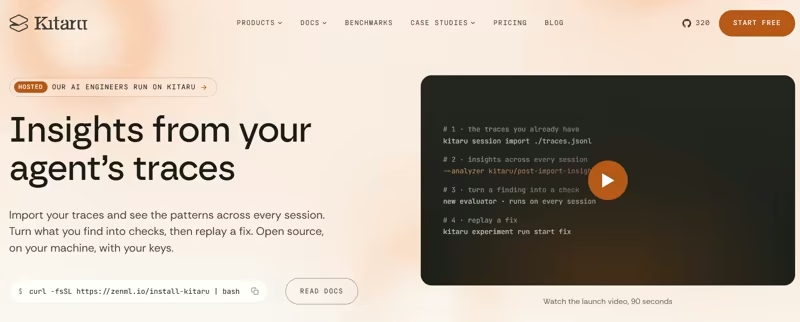
Kitaru, from ZenML Labs, is an open-source (Apache 2.0) tool for insights, evals, and replay on top of your agent’s traces.
As a DeepEval alternative, Kitaru changes where evaluation happens. Instead of scoring only hand-written test cases, it runs your evaluators on the sessions your app already recorded, shows you what your evals miss, and replays a fix against the sessions that failed. It doesn’t replace your judges: DeepEval metrics, pytest checks, and your own LLM judges run inside it as evaluators.
Key Feature 1. Run Your Evals on Real Traces
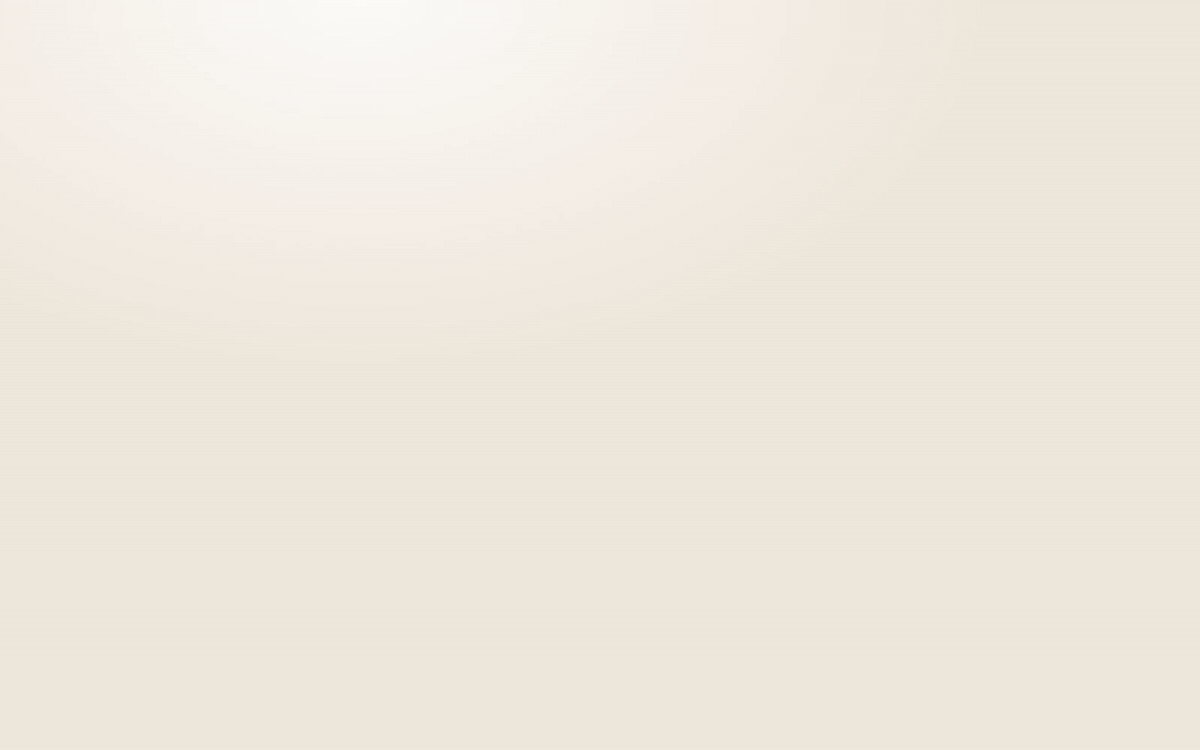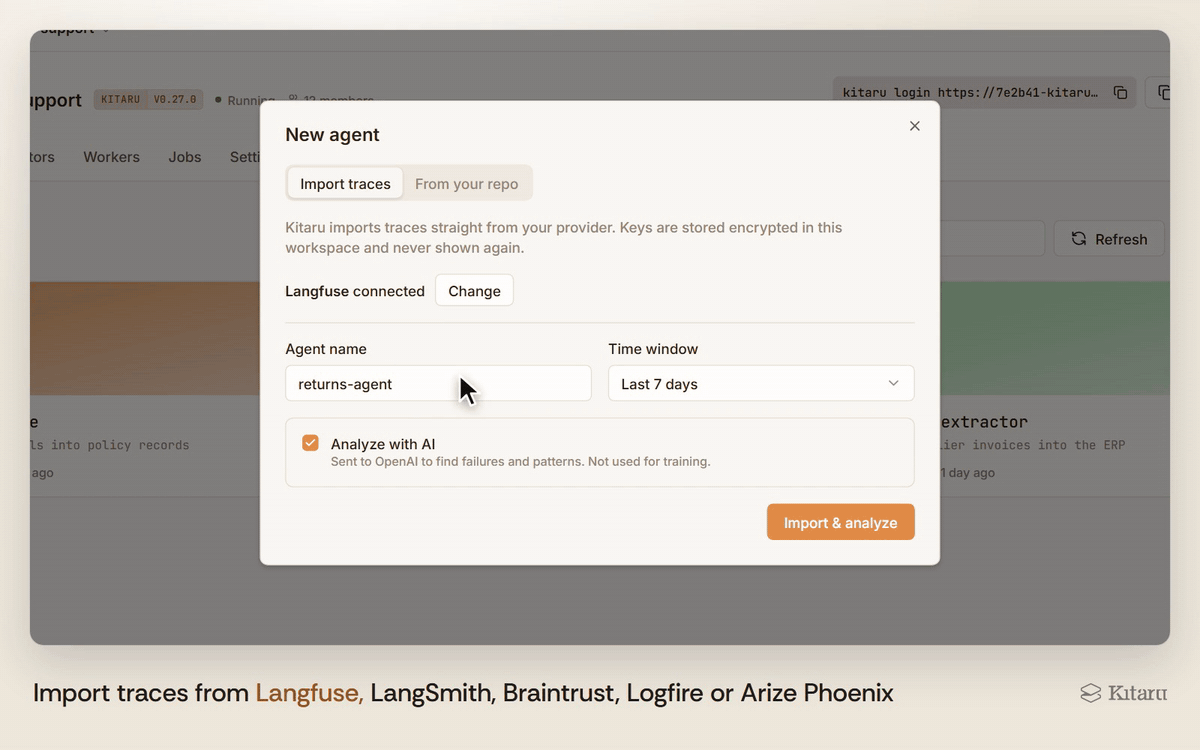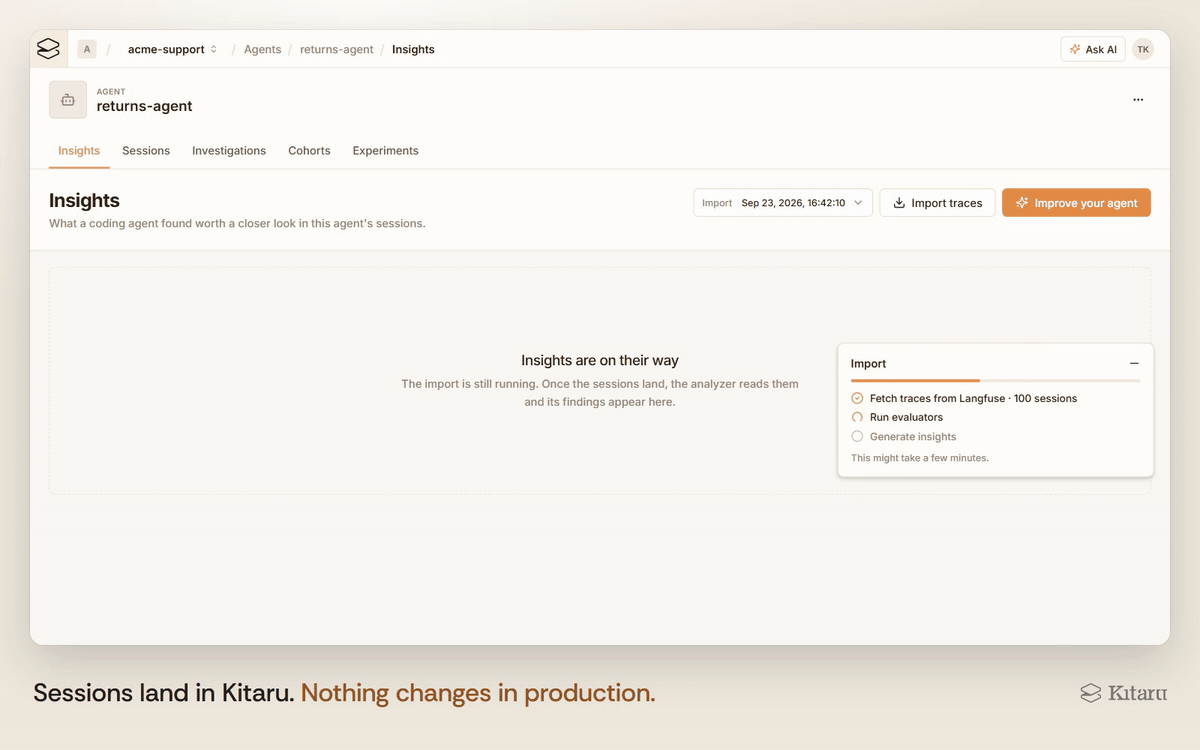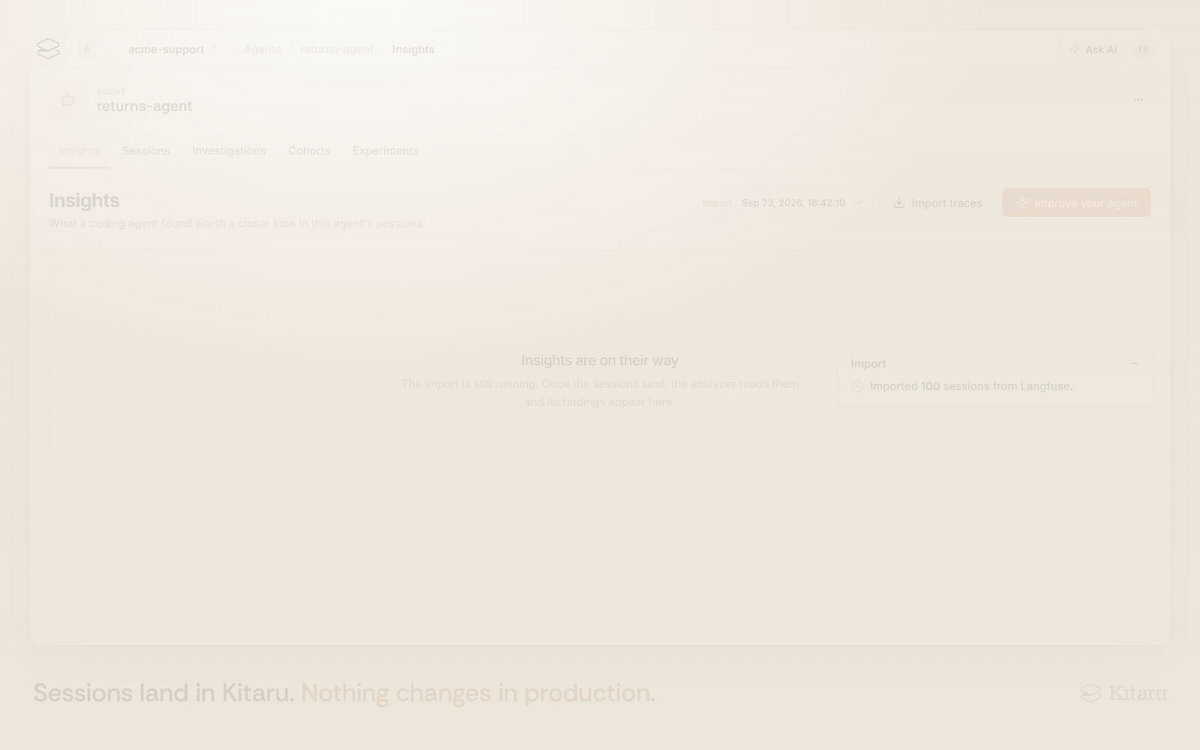
Kitaru imports the traces you already collect in Langfuse, LangSmith, Braintrust, Logfire, MLflow, or Arize Phoenix, with no code changes, and turns each one into a session. If you would rather record new runs, a one-line adapter wraps agents built with PydanticAI, the OpenAI Agents SDK, LangGraph, the Claude Agent SDK, Mastra, or the Vercel AI SDK.
With Kitaru’s evaluators, you can:
- Wrap the judges and tests you already run, DeepEval metrics included, as versioned Kitaru evaluators.
- Score every imported session in one batch, so each result sits on the session it judged.
- Write human labels as evaluations and compare them with your judge’s verdicts to calibrate it.
- See which sessions your judges pass but you would fail, and which behaviors no eval checks.
This turns evaluation from a fixed test suite into a check on what your app actually did in production.
Key Feature 2. Deterministic Checks Without a Judge Model
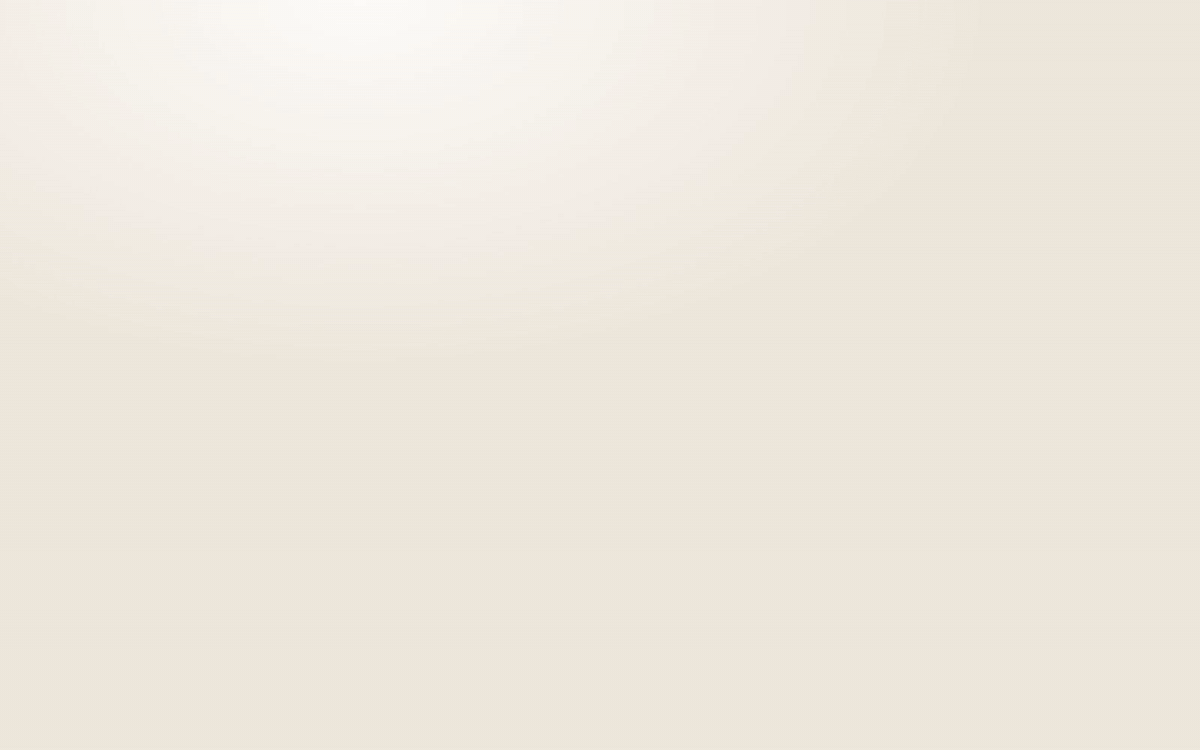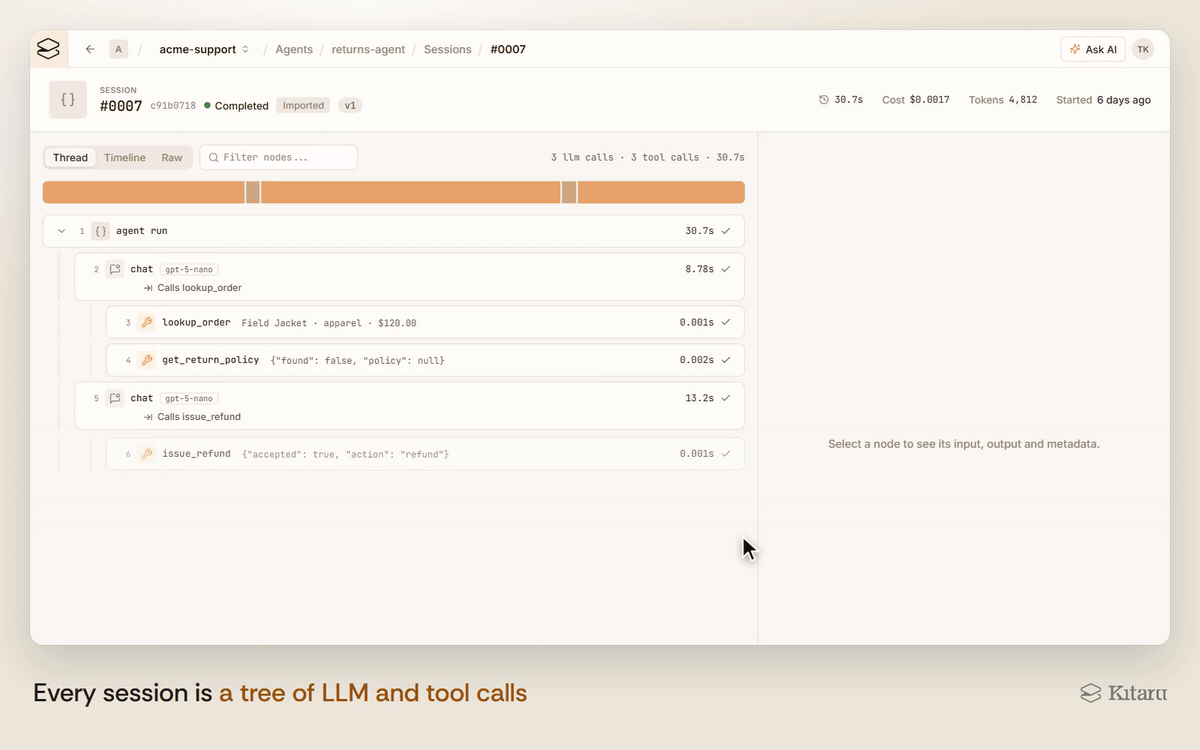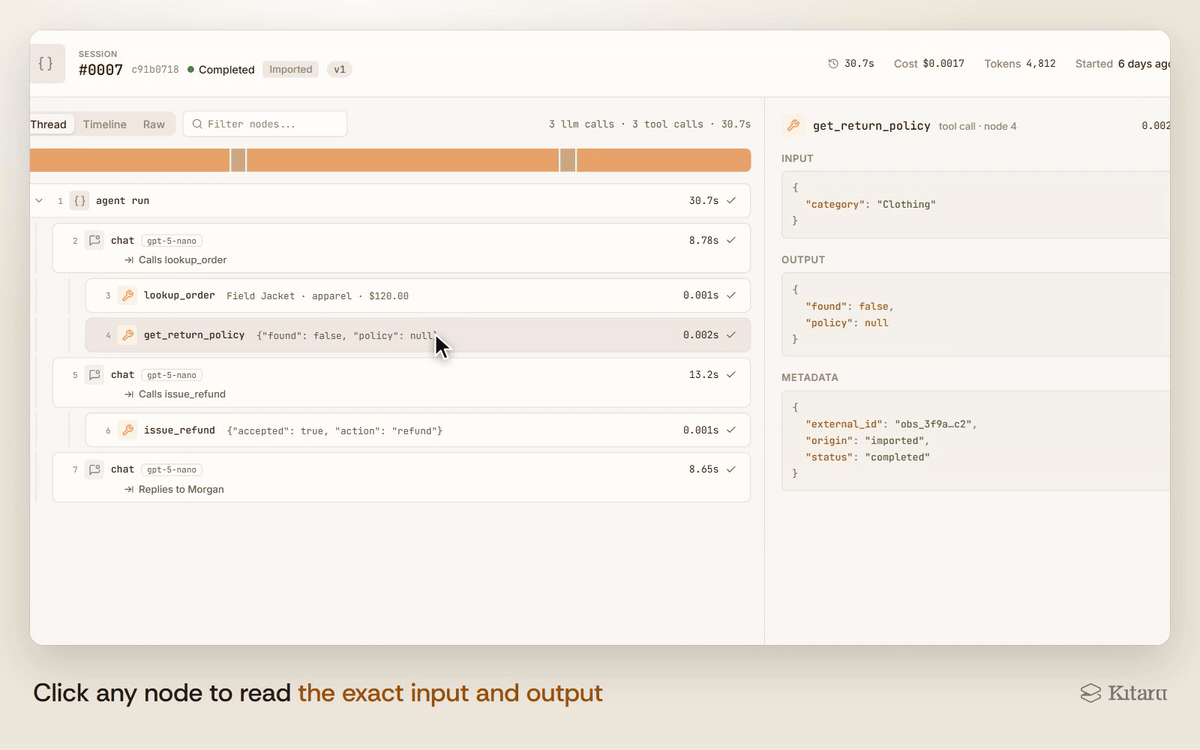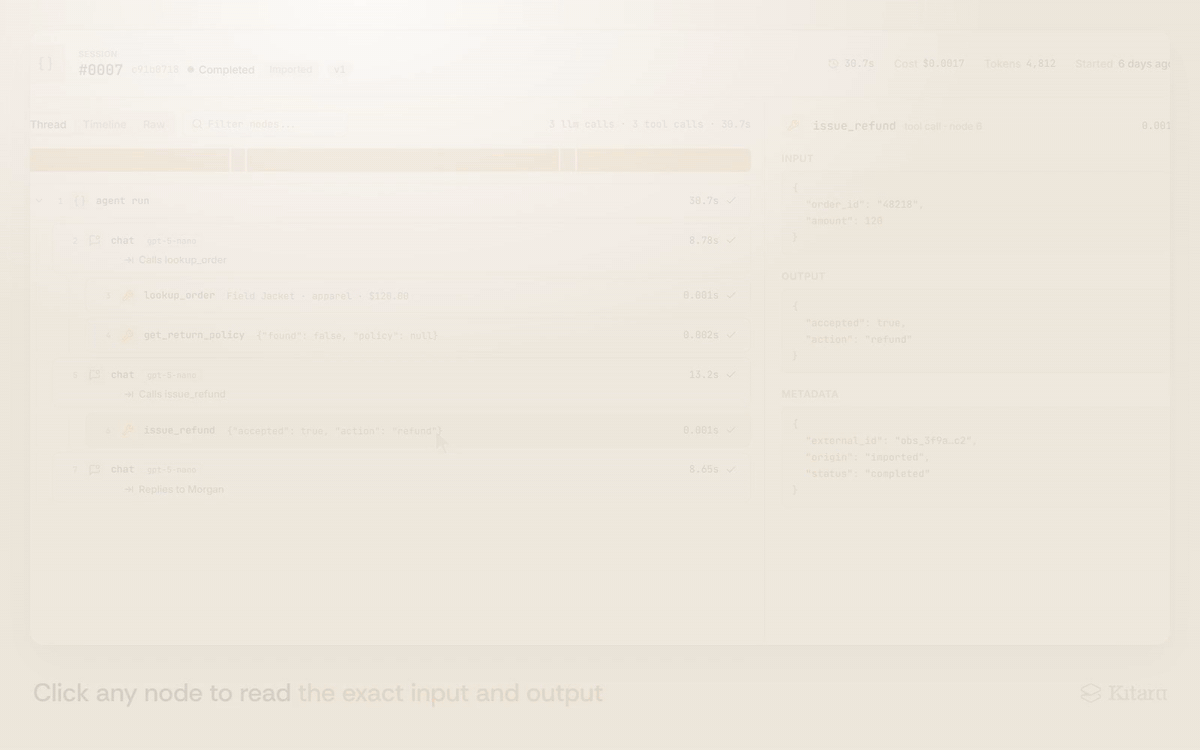
Kitaru’s answer to judge costs is a set of built-in checks that read the recording instead of calling a model. It registers ten deterministic evaluators at startup, plus three cheap signals for cost, latency, and tool-call patterns. They run in your deployment with no model API charge.
With the built-in evaluators, you can:
- Triage unfamiliar traces with bundles for session diagnostics, repeated tool calls, tool failures, timing, and failed LLM calls.
- Enforce rules you already have: output contracts, resource budgets (cost, tokens, duration, tool calls), allowed and forbidden tools, and allowed models.
- Check that an agent called the tools it should, in the order it should.
- Add a typed model judge (TypeSafe’s jev) or your own LLM judge only where a rule can’t decide, such as whether a reply invented a fact.
This keeps LLM-as-a-judge for the questions that need it and settles the rest with checks that cost nothing to run.
Key Feature 3. Replay a Fix and Gate It in CI
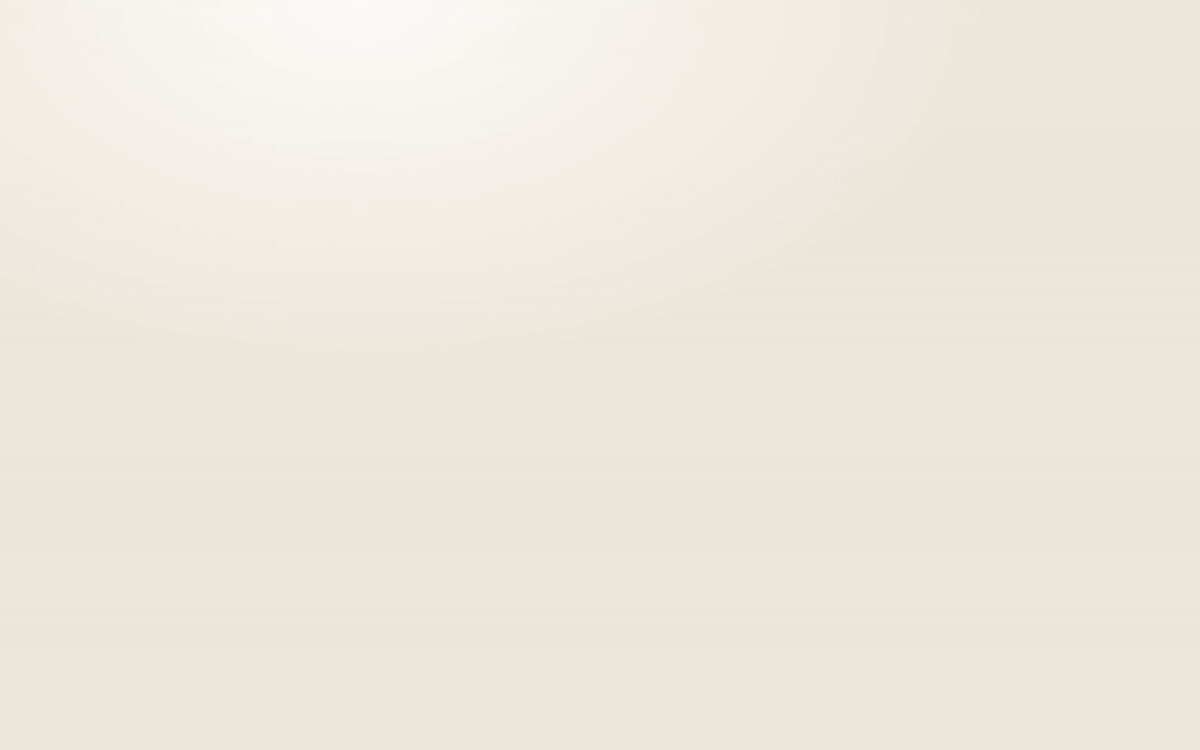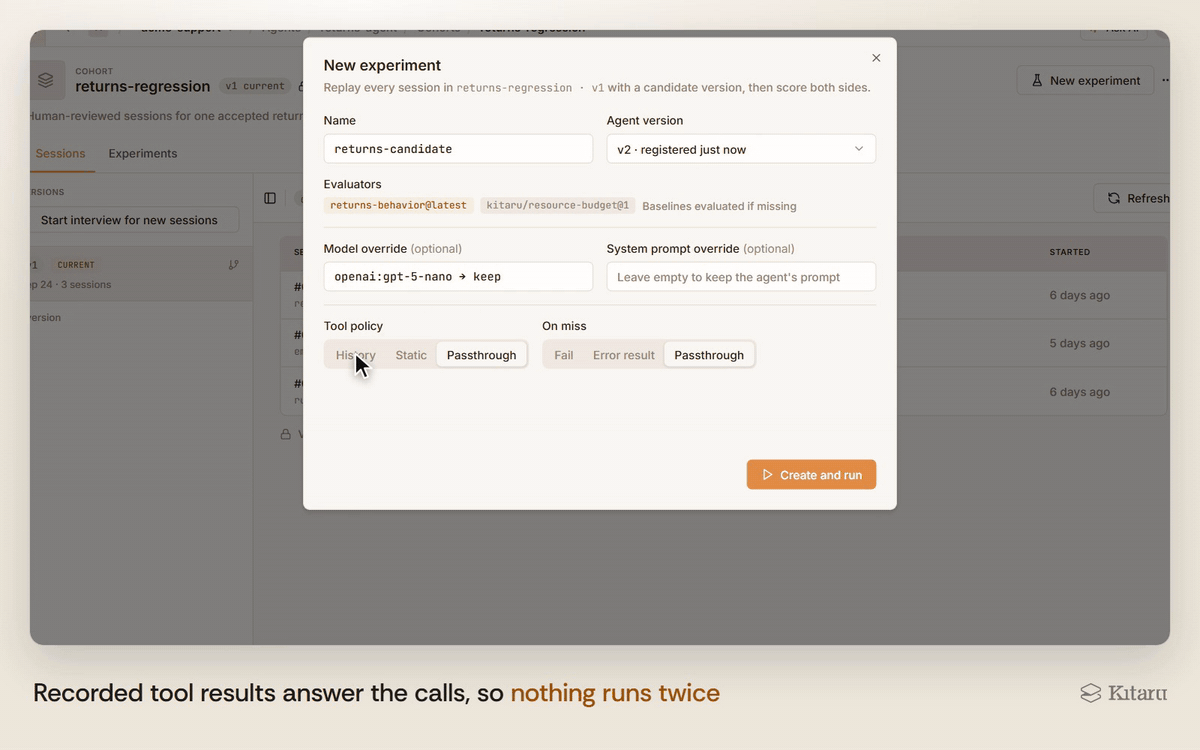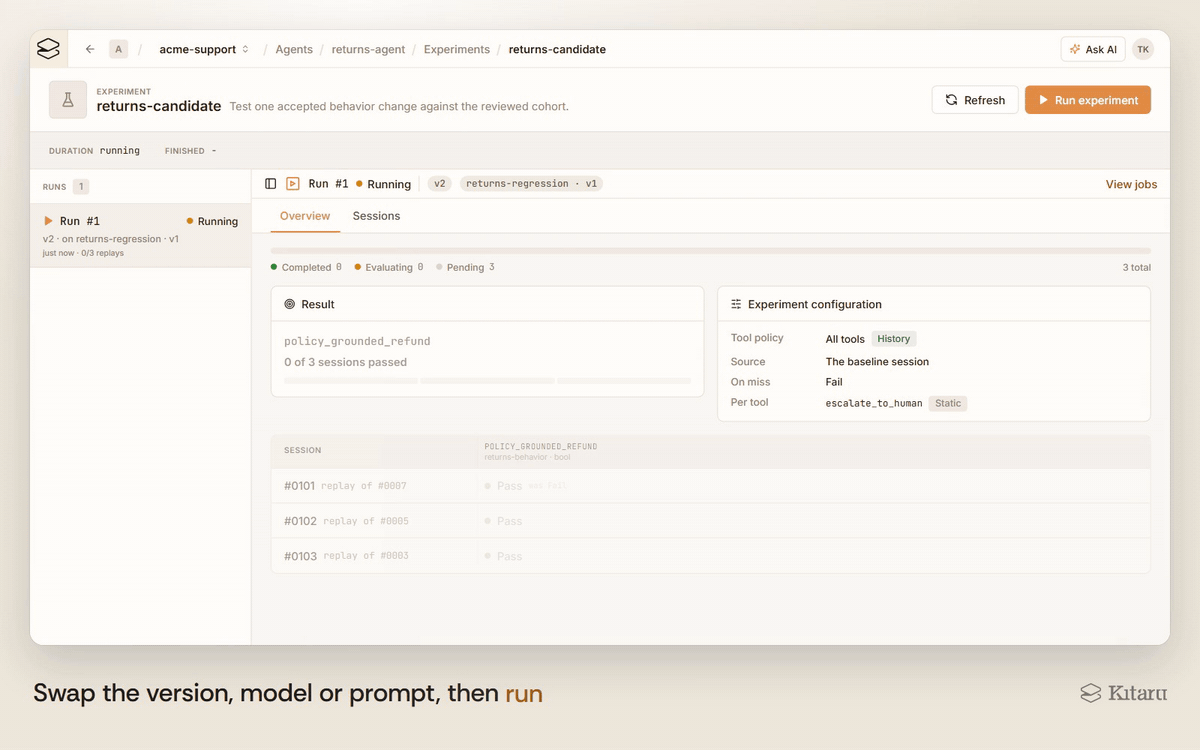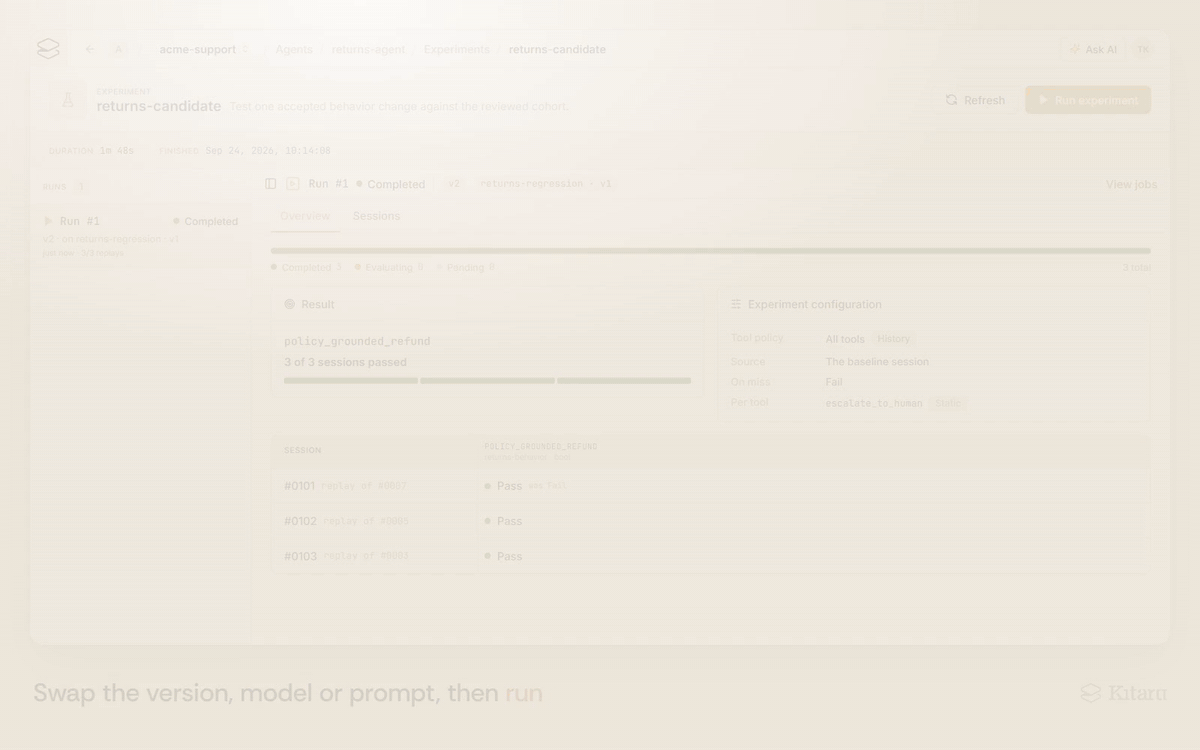
When you change a prompt, swap the model, or fix the code, Kitaru replays your agent on the sessions that failed. Your real code runs again, and with the history tool policy, tool calls are answered from the recording, so nothing touches live systems. Every replay and experiment runs at least one evaluator, so the result is scored the moment it lands.
With Kitaru experiments, you can:
- Freeze a cohort of failed or representative sessions so results stay comparable.
- Replay the cohort with one change and compare the baseline and the replay side by side.
- Check whether a cheaper model holds the same quality on the same sessions.
- Run the same experiment in CI:
kitaru experiment run start --waitexits nonzero if the run fails, so the job works as a gate.
This makes evaluation work like a regression suite built from production runs instead of hand-written test cases.
Pricing
Kitaru is free and open-source under the Apache 2.0 license. It runs on your machine with your own model keys, and replays call the providers you pick, so model costs stay on your own bill.
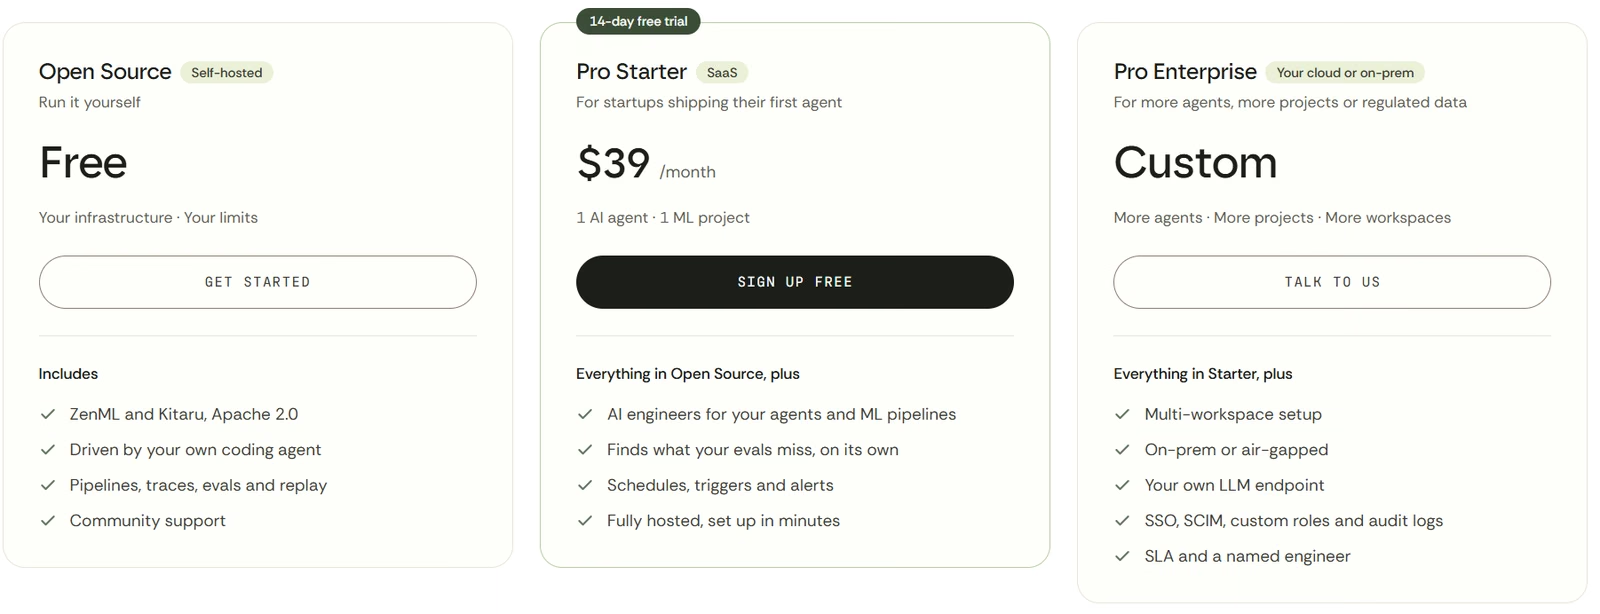
ZenML Pro, our paid platform, hosts Kitaru and ZenML for your team and adds AI engineers that read your traces next to your evals and flag wrong or missing ones. The Starter plan costs $39 per month for one AI agent and one ML project, with a 14-day free trial and no credit card. Enterprise is custom-priced and adds on-prem or air-gapped deployment, your own LLM endpoint, SSO, and audit logs.
Pros and Cons
Kitaru’s biggest pro is that it evaluates what your app actually did, not only the test cases you thought to write. Its deterministic evaluators cover many checks without a judge model, which cuts the cost problem that pushes teams away from DeepEval, and replay tests a fix against real sessions without touching live systems. It’s open source and runs locally with your own keys.
But Kitaru isn’t a metric library. Beyond its built-in checks and the typed jev judge, you bring your own LLM judges (DeepEval’s metrics work for that), and the jev judge sends session content to TypeSafe’s hosted API. It works on recorded sessions, so you need traces or an adapter first, and it’s in Beta, so interfaces may still change.
2. Ragas
Ragas is a lightweight, open-source evaluation toolkit purpose-built for RAG pipelines. It offers domain-specific metrics like context relevance, faithfulness, and semantic similarity scoring.
Features
- Score RAG outputs using context precision, recall, faithfulness, and response relevance to pinpoint retrieval or generation failures.
- Combine LLM and classic metrics like BLEU or ROUGE for accurate, semantic evaluations beyond surface-level text match.
- Generate synthetic test cases with question-answer pairs to evaluate pipelines without labeled datasets.
- Integrate into Python workflows with a LangChain-compatible API and simple dataframe inputs.
- Extend with custom metrics by adding your own evaluators and running tests in any script, notebook, or CI job.
Pricing
Ragas is completely free and open-source under the Apache 2.0 license. You only pay for LLM API calls used by LLM-based metrics, making it the most cost-effective option for RAG evaluation.
Pros and Cons
Ragas is excellent at RAG-specific evaluation. That level of insight is a major advantage over black-box evaluations done by DeepEval. Ragas is also highly extensible and open source, so you can adapt it as needed. Another pro is its simplicity; being code-first, you can integrate it into tests or scripts easily without a new UI to learn.
But keep in mind, Ragas focuses on RAG and isn’t much preferred for general LLM evaluation. If you’re spanning multiple patterns, you must combine Ragas with other evaluation tools.
3. TruLens
TruLens is an open-source framework that provides evaluation and tracing for LLM applications. Rather than DeepEval’s black-box evaluation, TruLens emphasizes explainability through feedback functions. It lets you compose logic from small, reusable feedback functions measuring groundedness, relevance, language match, and custom criteria.
Features
- Log every LLM call and trace nested chains with token usage, latency, and feedback scores across reasoning steps.
- Run built-in evals like groundedness, context relevance, and answer accuracy using LLM-based feedback functions.
- Compare multiple versions of prompts, chains, or models with side-by-side leaderboards and aggregate scores.
- Visualize traces and metrics in a local dashboard to spot failing cases and inspect intermediate outputs.
- Evaluate agent flows by capturing tool calls, sub-prompts, and intermediate reasoning steps in chain-of-thought logic.
Pricing
TruLens is completely free and open-source under the MIT license, with no usage fees or cloud hosting costs.
Pros and Cons
TruLens’s major pro is the rare combination of evaluation + tracing it provides. Many tools do one or the other, but TruLens does both, which means you get the ‘Why’ behind the scores. The local dashboard is a big plus for quick, interactive debugging of LLM behavior, which boosts developer productivity.
Building feedback functions requires more engineering effort than using DeepEval’s LLM-as-a-judge. You write more code defining quality criteria. Additionally, DeepEval lacks a built-in scheduler or database for long-term storage, relying solely on its local usage.
4. Promptfoo
Promptfoo is a lightweight prompt evaluation framework built for fast iteration and regression testing. It’s ideal for developers who want to track prompt quality, benchmark across models, and automate prompt testing in CI, all without complex setup.
Promptfoo is now part of OpenAI, which announced the acquisition on March 9, 2026, and the CLI and library continue as an open-source project.
Features
- Run prompt tests locally or in CI to validate outputs across models, prompts, or datasets with clear pass/fail results.
- Define test cases declaratively in YAML and compare models side-by-side for variations with diff views and without extensive coding.
- Run automated security scans detecting jailbreaks, prompt injections, and data leakage across models.
- Score generations automatically using exact match, regex, LLM-based, or custom evaluators.
Pricing
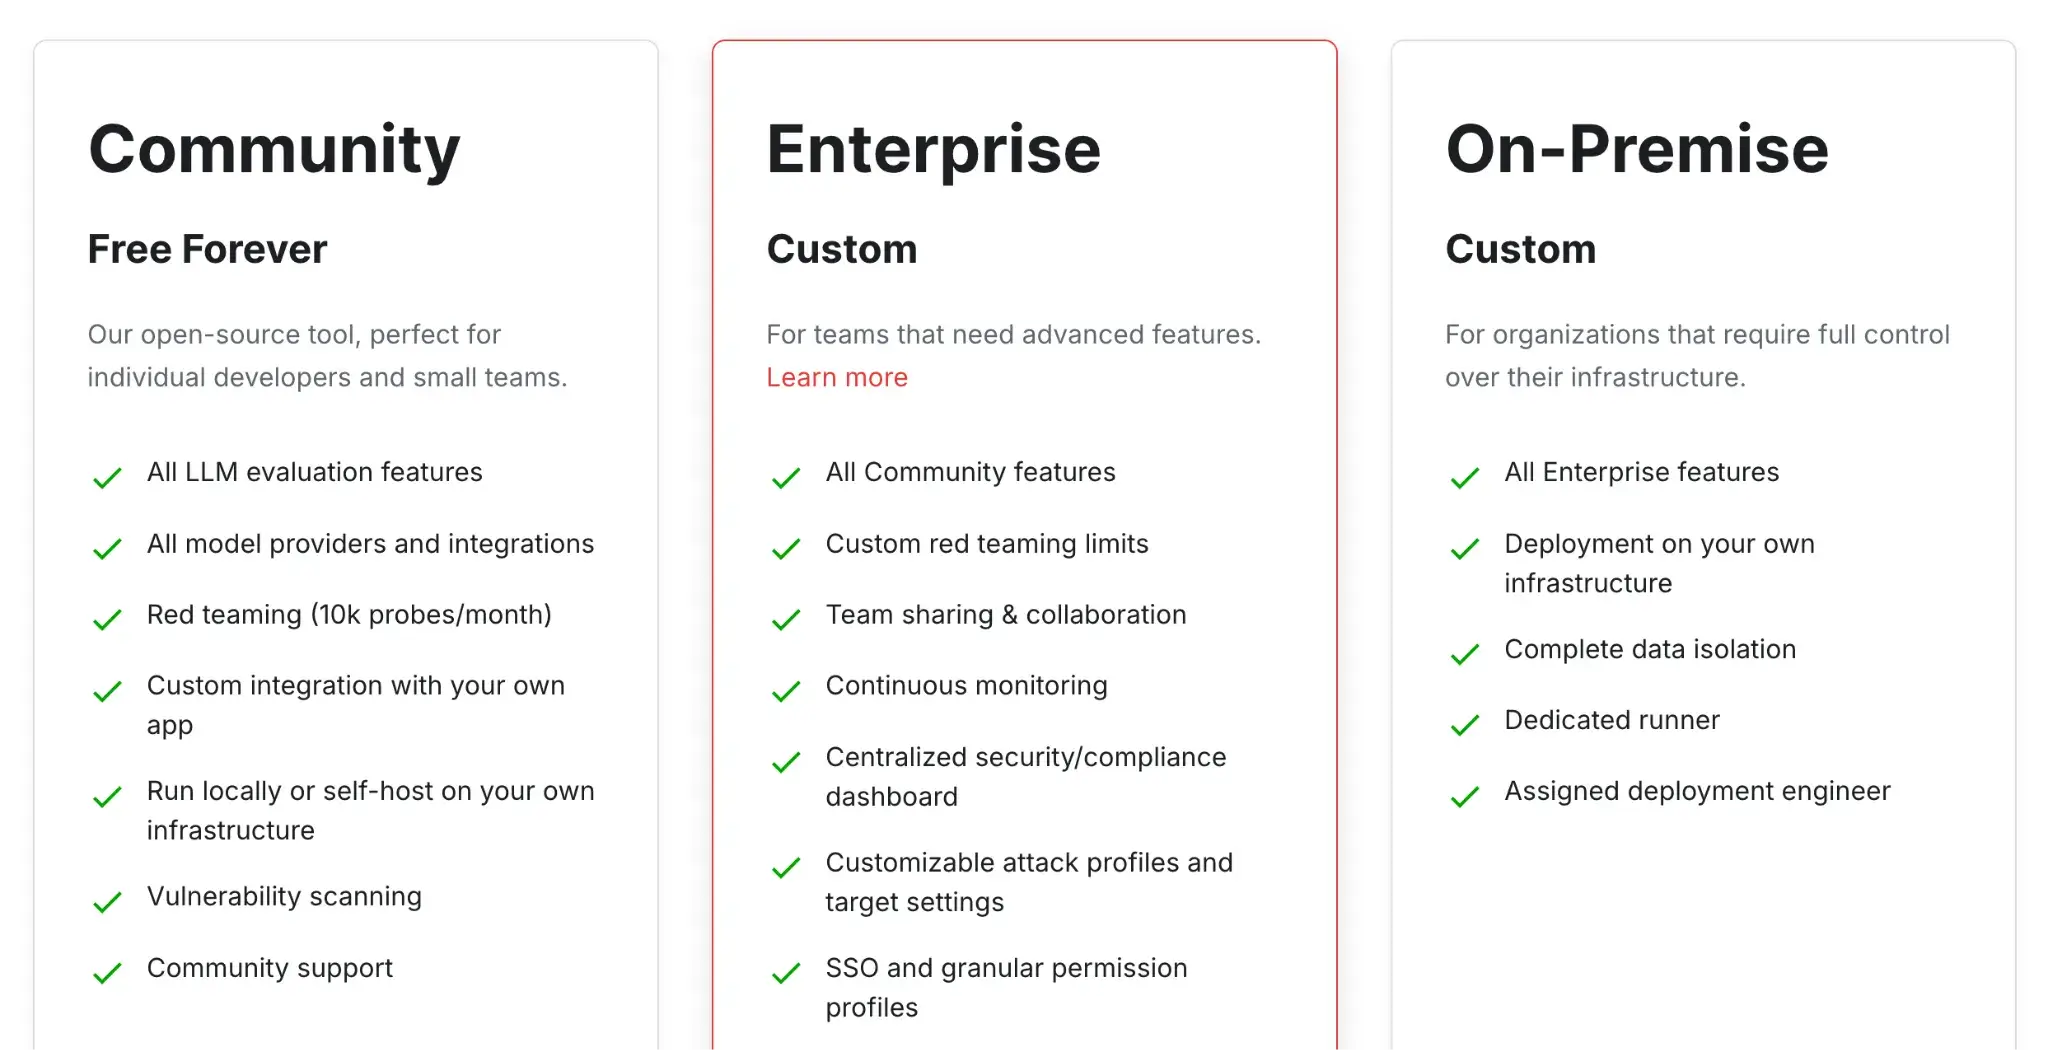
Promptfoo is completely free and open-source under the MIT license. Paid cloud hosting is available for team collaboration and result sharing.
Pros and Cons
Promptfoo is great for prompt engineers and devs who want no-fuss regression testing and clear test case visibility. Its strength lies in fast, model-agnostic evaluations with a focus on automation and repeatability.
However, it lacks deeper observability features like session tracking or UI-based prompt management. More of the reason why it’s better suited for smaller apps or early-stage LLM workflows.
5. Arize Phoenix
Arize Phoenix is an open-source observability platform from Arize AI. It captures traces through OpenTelemetry, enabling you to debug agent behavior, perform what-if analysis, and evaluate quality across runs. Its trace-first approach allows for quicker debugging visibility for complex LLM systems.
Dynatrace completed its acquisition of Arize on October 1, 2026, and Arize continues to support Phoenix as its open-source platform.
Features
- Log every LLM call with OpenTelemetry-based traces to capture nested tool usage, latency, and full multi-step flows.
- Run LLM-based evals on response quality, context relevance, and hallucinations using built-in or custom metrics.
- Track prompt experiments by comparing model versions or prompt changes across versioned datasets.
- Test prompts in the playground and replay past traces with edits to iterate quickly and A/B test variations.
- Inspect outputs visually in a local dashboard with filters, annotations, and detailed input/output breakdowns.
Pricing
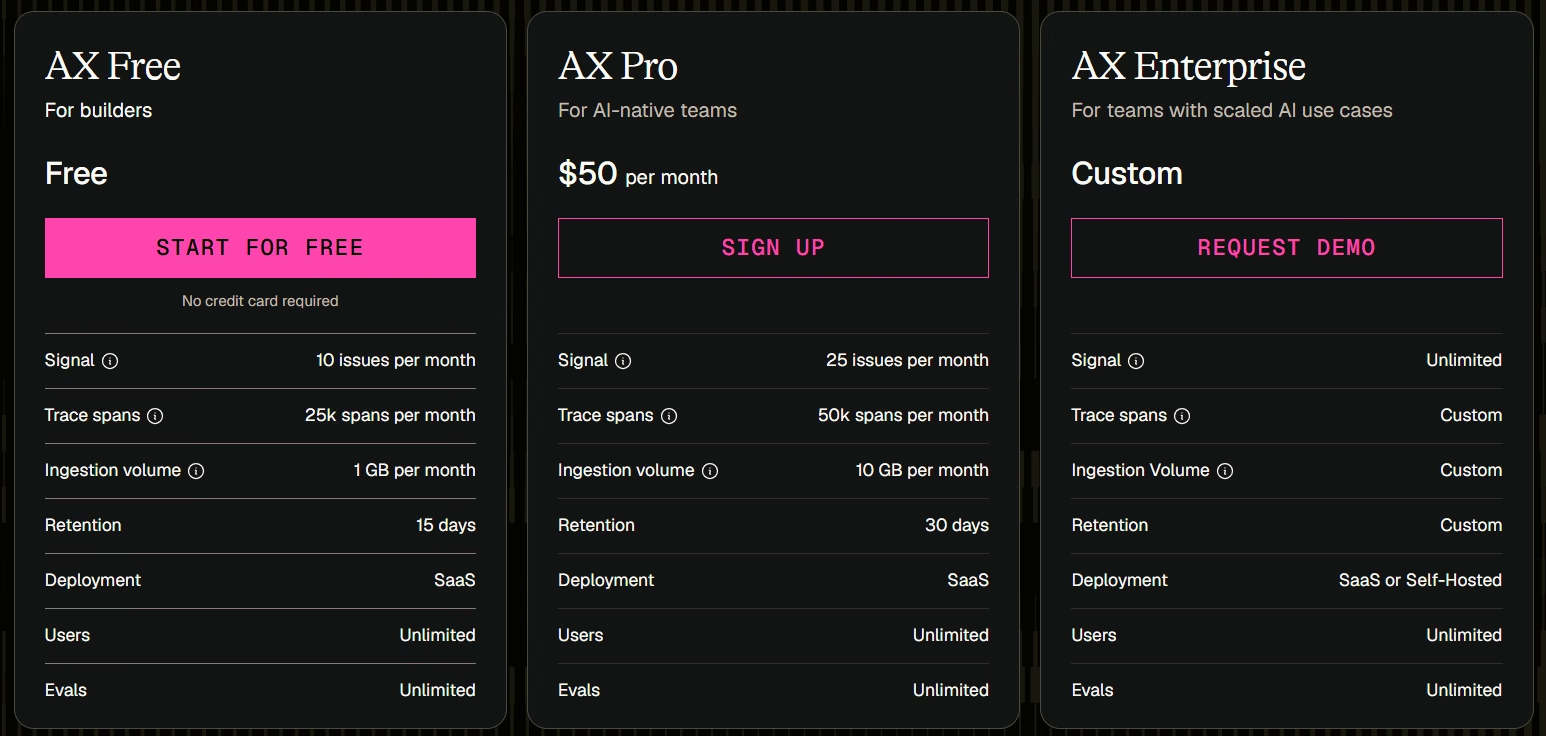
Arize Phoenix is free to self-host with no limit on the number of users. On top of that, it offers a free SaaS (cloud-hosted) plan for solo developers, and two paid plans:
- AX Pro: $50 per month
- AX Enterprise: Custom pricing
Pros and Cons
Phoenix’s strength is trace-first observability. If you need step-by-step visibility into your LLM app, Phoenix is great for it. OpenTelemetry foundation ensures cross-framework compatibility. Plus, it’s framework-agnostic and integrates well with LangChain, LlamaIndex, and others, making it easy to slot into most LLM stacks.
But Phoenix is observability-first. Its pre-built evaluators cover faithfulness, hallucination, toxicity, retrieval relevance, and tool calling, and it now includes versioned datasets, experiments, and prompt management. For a deeper RAG metric suite like RAGAS, you still add a separate library.
6. Langfuse
Langfuse is an open-source LLM engineering platform that directly competes in the space of LangSmith and Phoenix. It helps teams trace, evaluate, and manage prompts for LLM applications.
ClickHouse acquired Langfuse on January 16, 2026. Langfuse says its roadmap stays the same and that it remains committed to open source and self-hosting.
Features
- Trace all LLM calls, including nested calls, with automatic token counting and cost calculation across different model providers.
- Version and manage prompts independently from code with version-controlled templates and rollout tracking.
- Run automated evals using LLM-based or rule-based metrics like accuracy, cost, groundedness, or latency thresholds.
- Collaborate on traces by sharing, commenting, and labeling sessions directly in the Langfuse UI.
- Support multi-modal traces, including text, images, and audio, for better observability.
Pricing
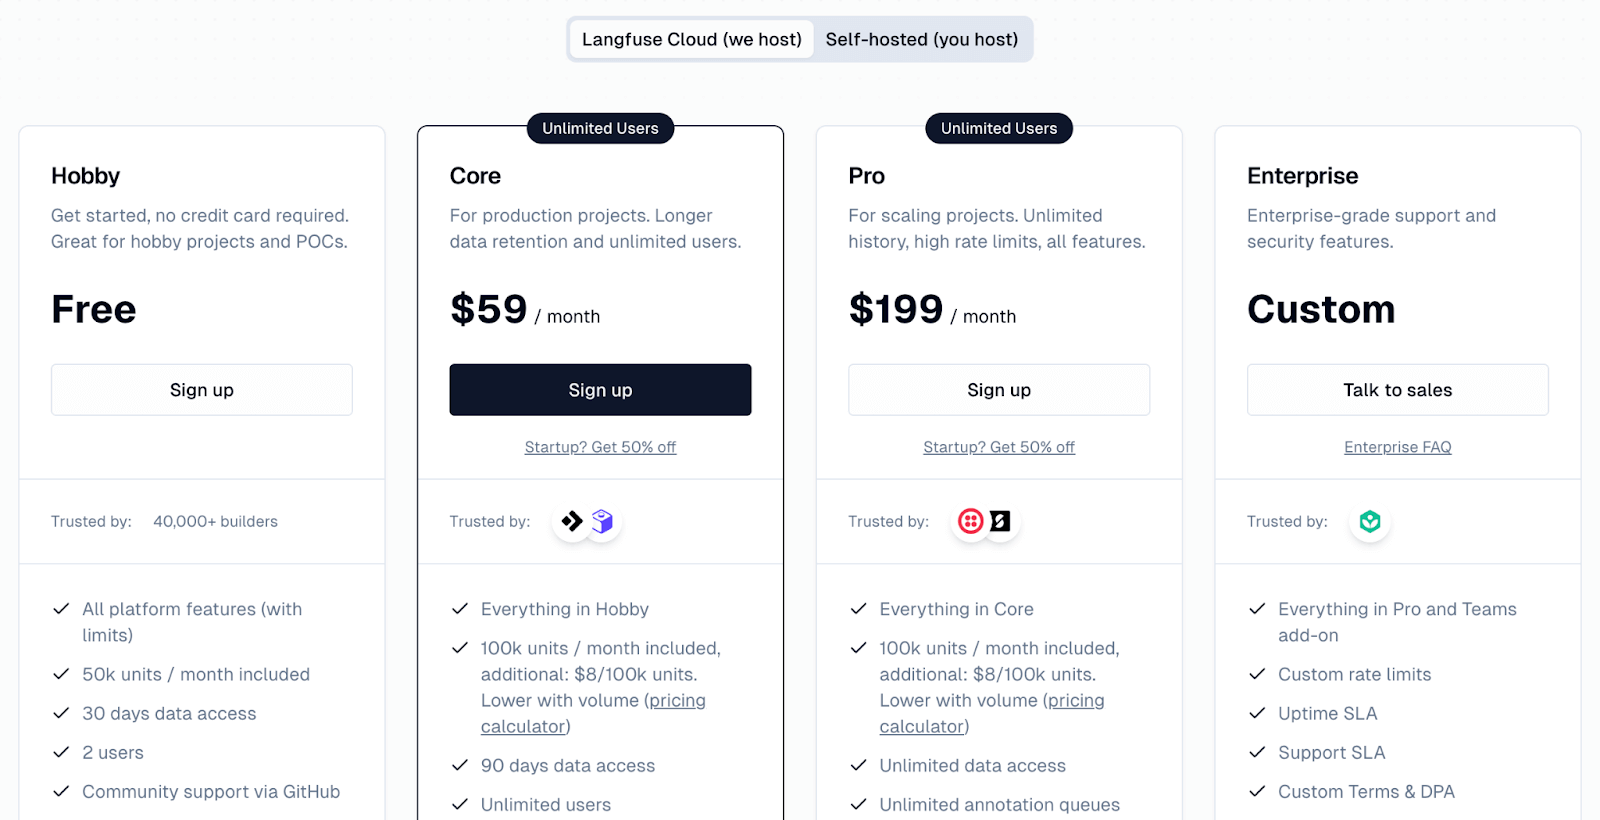
Langfuse is free to use and open-source for self-hosting. Langfuse Cloud offers a free Hobby tier and three paid plans:
- Core: $29 per month
- Pro: $199 per month
- Enterprise: $2499 per month
Pros and Cons
Langfuse combines trace-level visibility with evaluation tools in a beautiful UI. It’s open-source, easy to self-host, and includes versioned prompt tracking and collaborative debugging, too. Besides, DeepEval integration lets you use Langfuse’s tracing with DeepEval metrics.
The framework focuses primarily on the LLM layer, so it doesn’t cover full ML pipelines or training workflows. You’re layering tools for an all-in-one evaluation and tracing solution. You need to integrate multiple libraries rather than using one unified framework. This also makes the initial setup heavier than simpler tools like DeepEval.
7. Evidently
Evidently is an open-source evaluation and observability framework for LLM apps, RAG pipelines, AI agents, and ML models. It combines rule-based checks, classifiers, and LLM judges, and adds the data drift detection it built for predictive ML.
Features
- Choose from 100+ built-in metrics, including hallucination and factuality, retrieval quality and context relevance, PII detection, toxicity, and adherence to guidelines and format.
- Combine rules, classifiers, and LLM-based evaluations, and write custom LLM judges with your own prompt and model, or use Hugging Face models as evaluators.
- Generate synthetic test data, including RAG evaluation datasets and adversarial inputs, to test edge cases before release.
- Detect data drift with the built-in Data Drift preset and configurable drift detection methods.
- Turn evals into pass/fail tests you can run in CI, and track results over time in a self-hosted dashboard, with tracing for live LLM apps.
Pricing
Evidently is completely free and open-source under the Apache 2.0 license, including the self-hosted Evidently Platform. Evidently Cloud is no longer offered as a SaaS product; Evidently Enterprise (Self-Hosted) is available for teams that need more.
Pros and Cons
Evidently is built for teams that want evaluations and monitoring without relying solely on LLM-as-a-judge. You can mix rule-based checks, classifier models, and LLM judges in one evaluation, and the same tool tracks drift in classic ML models, which suits teams that run both.
Evidently is broader than an LLM evaluation library, so its descriptors, reports, and tests take more setup than DeepEval’s pytest-style test cases. And since Evidently Cloud is no longer offered as a SaaS product, you self-host the platform for dashboards and monitoring.
8. LangSmith
LangSmith is LangChain’s commercial observability platform. It’s a managed SaaS platform developed by the LangChain team. It’s deeply integrated with the LangChain ecosystem and designed to track prompts, sessions, and evaluation signals across development and production environments.
Features
- Log every LLM call with detailed spans, inputs, outputs, errors, and nested tool usage for complete traceability.
- Version prompts and chains to run reproducible experiments and compare output quality over time.
- Run feedback-based evals using LLM, human, or rule-based scoring to analyze accuracy, relevance, and safety.
- Explore traces and metrics in an interactive UI that supports filtering, tagging, and multi-turn debugging.
- Integrate with LangChain directly for zero-config setup across agents, chains, and tools.
Pricing
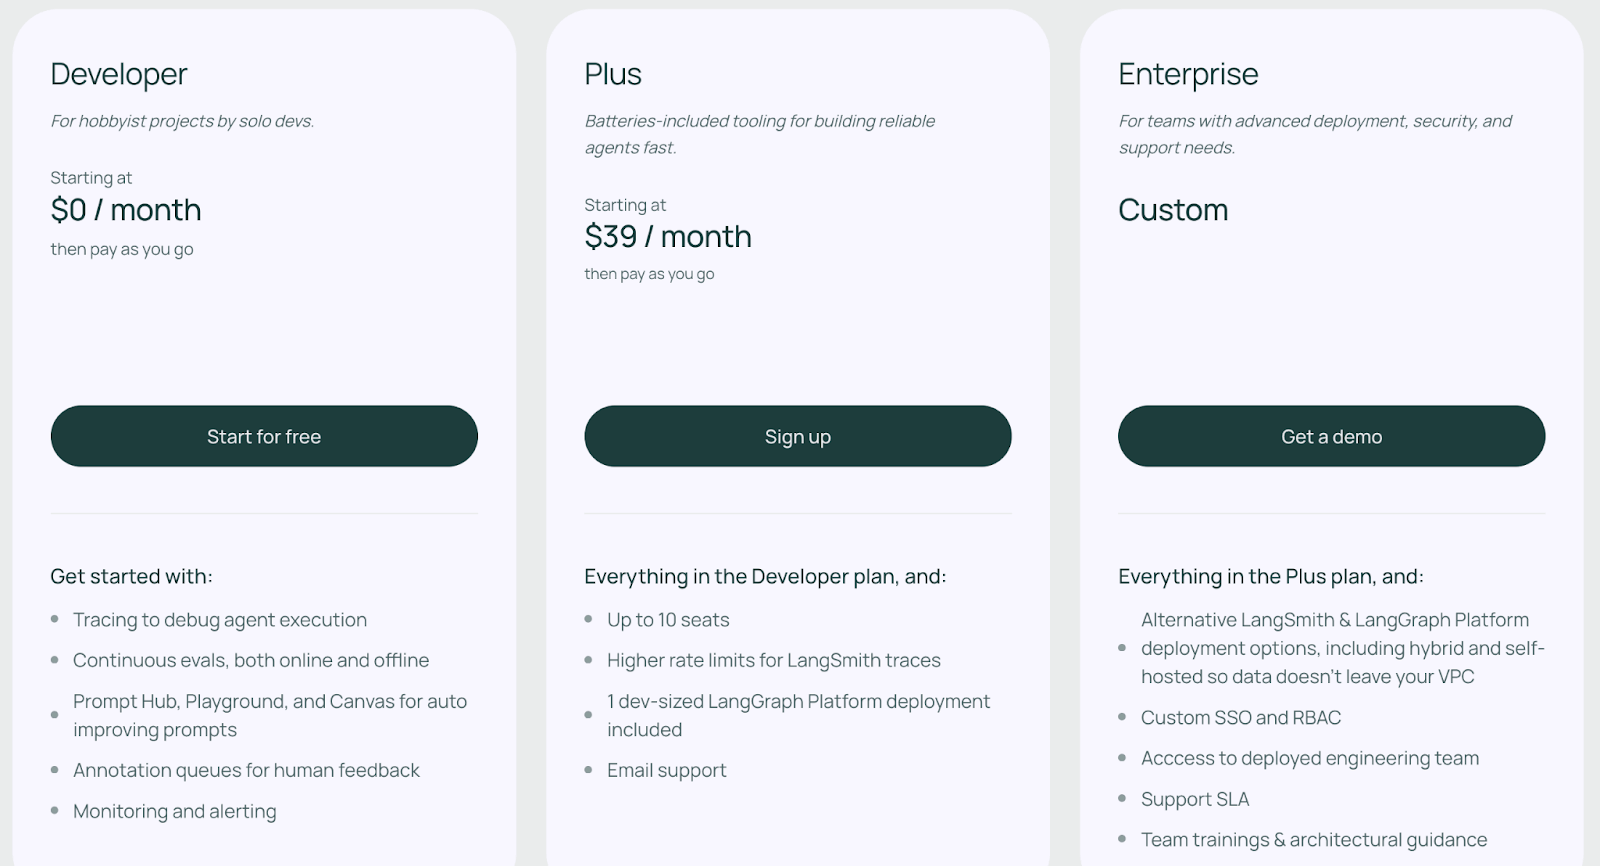
Langsmith offers a free developer plan and two paid plans:
- Plus: $39 per seat per month
- Enterprise: Custom pricing
Pros and Cons
LangSmith’s biggest pro is its plug-and-play observability option for teams already invested in LangChain. Its UI is highly polished and easy to use. The managed service handles infrastructure and scaling automatically, reducing operational burden.
However, being a managed SaaS platform comes with trade-offs. Pricing scales with trace volume, and there’s no open-source self-hosting option, except for the enterprise plan. Governance and data privacy are also concerns for regulated industries.
The Best DeepEval Alternatives for LLM Observability
Each of these DeepEval alternatives addresses a unique challenge of LLM evaluation and observability. So the best choice depends on your priorities. Here are our recommendations:
- For teams focused on RAG evaluation, Ragas offers the most targeted metric suite with lower costs than LLM-as-judge approaches.
- For those needing an explainable evaluation, TruLens provides a transparent feedback function framework where every decision is auditable.
- For teams that want to run their evals on real traces and test fixes before they ship, Kitaru runs your judges, DeepEval included, on the sessions your app already recorded and replays a fix against the ones that failed.
📚 Relevant alternative articles to read:
Take your AI agent projects to the next level with Kitaru and ZenML.
Install Kitaru with one command (curl -fsSL https://zenml.io/install-kitaru | bash), import the traces you already have, and see what your evals miss before you replay a fix.
We have built first-class support for agentic frameworks (like CrewAI, LangGraph, and more) inside ZenML, for our users who like pushing boundaries of what AI agents can do.
With ZenML, you can seamlessly integrate whichever agent framework you choose into robust, production-grade workflows.
- AI engineers on your agent
- Set up in minutes
- No credit card